Featured Publications
All Publications

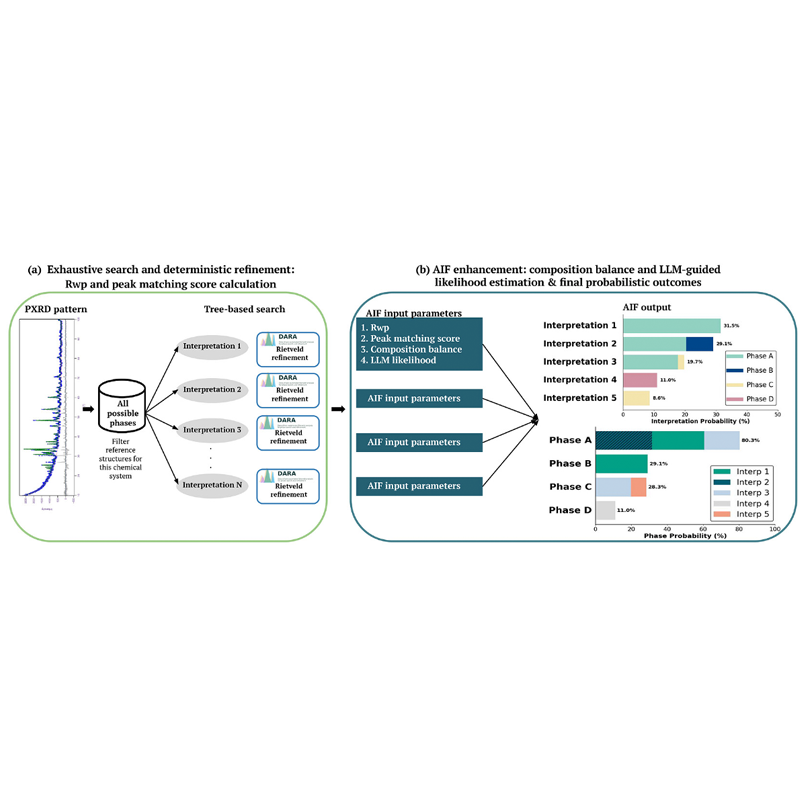
Autonomous laboratories increasingly enable materials synthesis at scale, but traditional high-throughput characterization workflows remain limited by the need for expert chemical intuition to distinguish plausible interpretations from formally good but chemically incorrect fits. We present an automated interpretation framework that combines probabilistic inference with automated chemical reasoning for phase identification from powder x-ray diffraction (PXRD). The framework evaluates multiple candidate interpretations using diffraction pattern-based metrics. It then refines these likelihoods using chemically-informed priors derived from composition balance and a large language model (LLM)–based plausibility estimate with human-readable justification and also produces a trustworthiness score. In a blinded multi-project benchmark, the framework's top-ranked interpretation was selected over the lowest-𝑅wp baseline in 93% of cases where evaluators expressed a clear preference (95% CI: [78%, 98%], 𝑛 =30). Trust decisions made by the framework aligned with expert judgment in approximately 75%–80% of cases. In a second evaluation, the framework systematically identified cases where lowest-𝑅wp interpretations were chemically implausible and surfaced credible alternatives to historically ambiguous samples. By reframing phase identification as a problem of probabilistic reasoning and trust-aware decision making, this work demonstrates how chemical intuition can be automated and scaled.
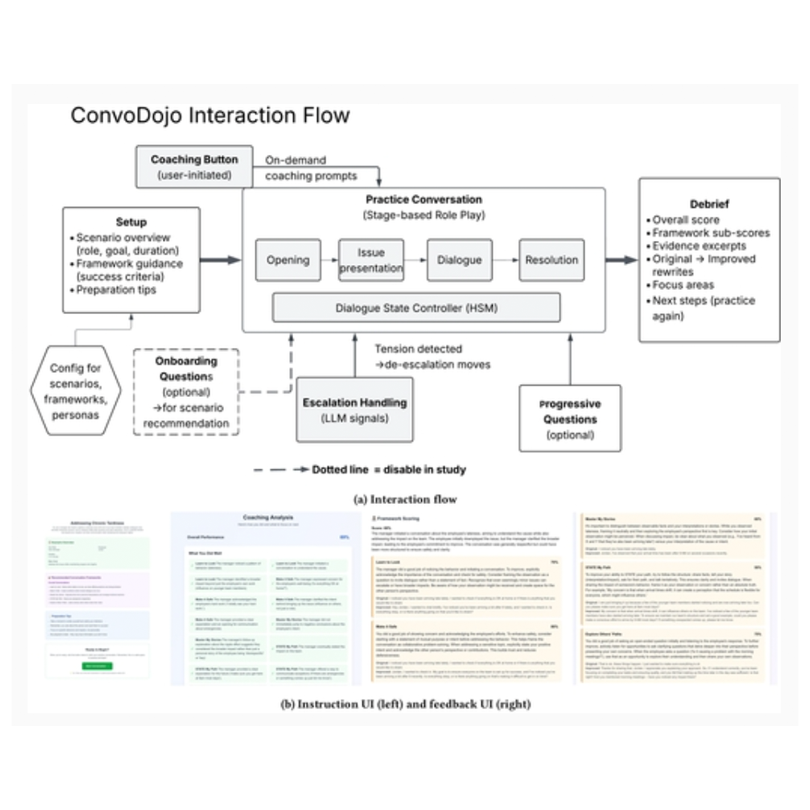
Large language models (LLMs) often exhibit sycophancy, optimizing for agreement over productive challenge, which severely limits their utility in domains like professional skills training, where growth requires pushback. We introduce, ConvoDojo, a novel conversational AI platform for practicing difficult workplace conversations, engineered not merely as a commercial training application but also as a flexible, instrumented research platform for evaluating conversational AI strategies. ConvoDojo repurposes LLMs as structured sparring partners to support skill development in difficult workplace conversations (e.g., performance feedback, conflict resolution), addressing the reported managerial tendency to avoid them. This paper showcases the platform and presents an evaluation of how key conversational user interface (CUI) design elements, namely, the addition of structured feedback and upfront instructional scaffolding, impact managers’ learning. Results show that ConvoDojo is highly engaging and promotes user reflection. We demonstrate how theory-informed dialogue and adaptive pushback can transform an LLM into an effective, measurable tool for complex communication skills development.
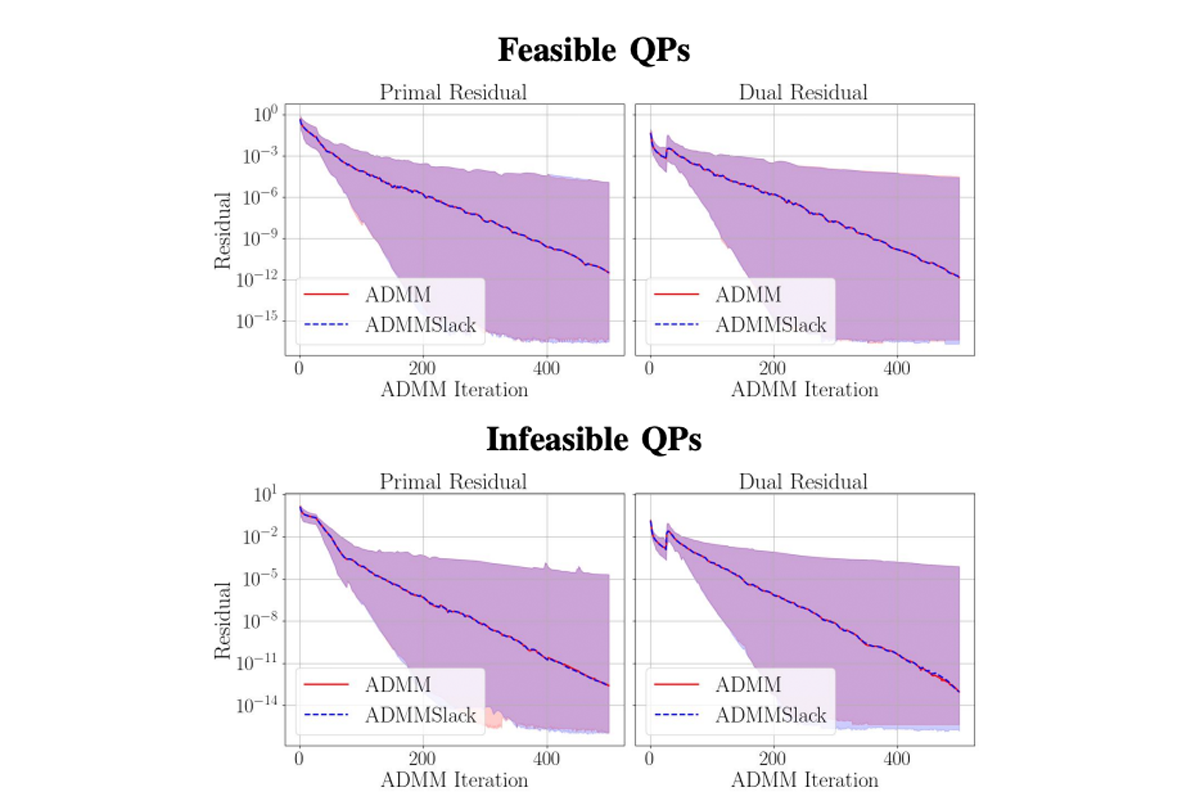
Proximal methods such as the Alternating Direction Method of Multipliers (ADMM) are effective at solving constrained quadratic programs (QPs). To tackle infeasible QPs, slack variables are often introduced to ensure feasibility, which changes the structure of the problem, increases its size, and slows down numerical resolution. In this letter, we propose a simple ADMM scheme to tackle QPs with slack variables without increasing the size of the original problem. The only modification is a slightly different projection in the z-update, while the rest of the algorithm remains standard. We prove that the method is equivalent to applying ADMM to the QP with additional slack variables, even though slack variables are not added. Numerical experiments show speedups of the approach.
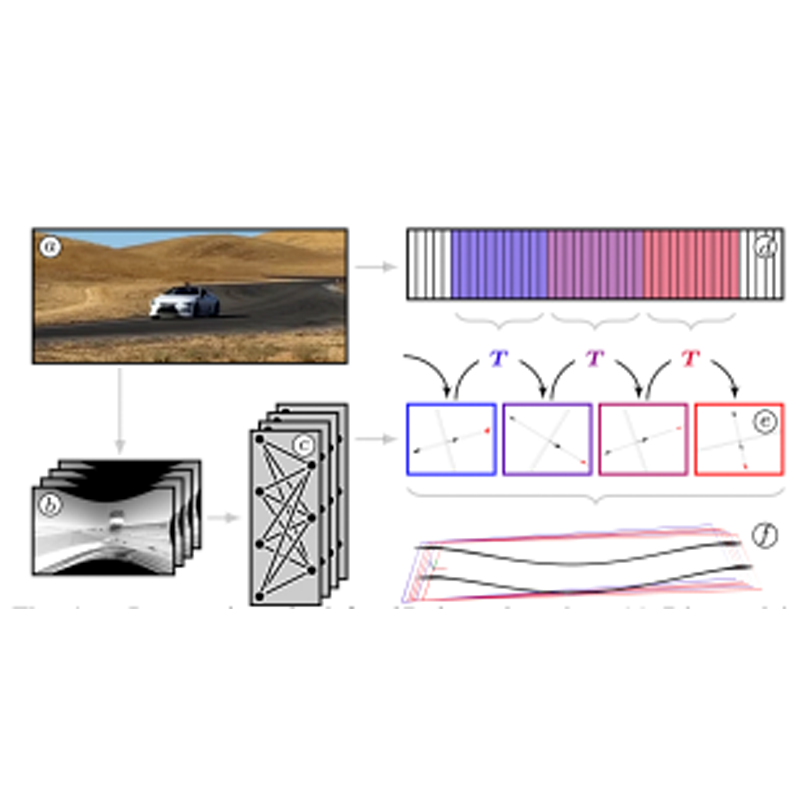
Lane boundary detection is a critical component in autonomous driving systems and has been rigorously studied in regular driving scenarios. However, it is less explored in vehicle racing, where the car moves at higher speeds across more extreme road geometries. To study this problem, we introduce a new dataset for 3D lane detection in racing, featuring >250k images from multiple camera feeds and inertial measurements taken with a Lexus LC 500 driving on a closed circuit. With this dataset, we compare various approaches to 3D lane detection and propose modifications that permit frames to be processed at rates of almost 300Hz while retaining high predictive performance in the racing application. This facilitates a multi-camera ensemble approach that is validated on hardware. We show that sensing modalities such as inertial measurements can be leveraged for pre-integration to regress road geometries over both cameras and time, yielding improvements in key metrics. Compared to methods such as BevLaneDet, adding odometry and ensemble predictions improves the F1 score by 3 points and reduces near-vehicle mean absolute errors (MAEs) by >30%. We show F1 scores >0.9 and lateral MAEs of <0.18m in vehicle deployments.
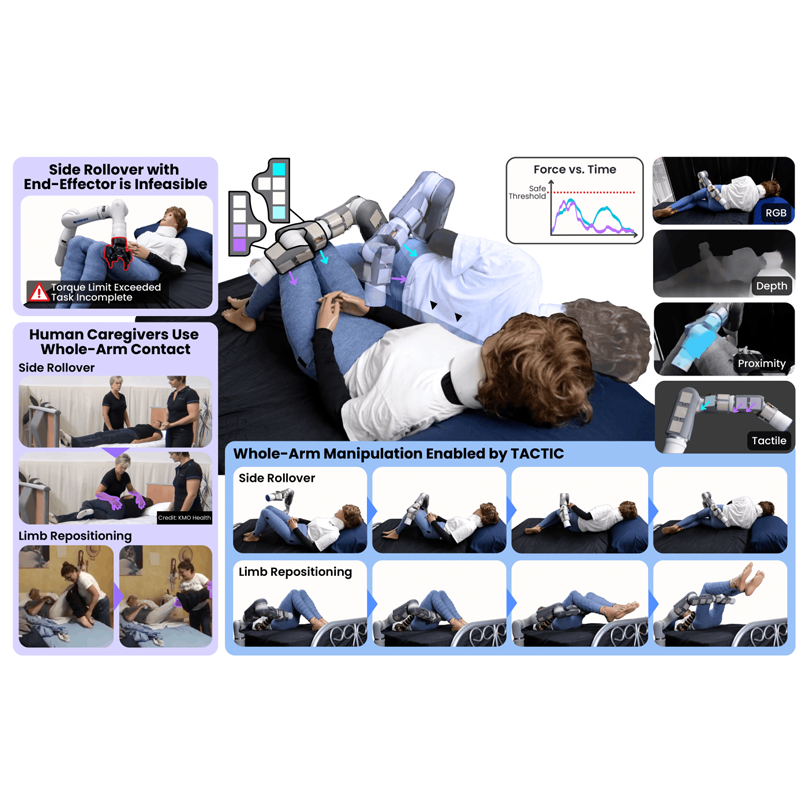
Whole-arm manipulation involves direct contact with the environment while the robot completes a task by distributing contact across multiple links as contacts form, slide, and break. This setting breaks common implicit assumptions in many learning-based manipulation pipelines: arm configuration tightly couples motion and contact forces, contact state is partially observed under occlusion, and purely learned rollouts can become physically inconsistent under distribution shift because many multi-link contact configurations are sparsely represented in the data. To address this, we propose TACTIC (Tactile and Vision Conditioned Contact-Centric Control), a receding-horizon controller for whole-arm manipulation. TACTIC uses a contact-centric hybrid predictive model that combines RGB-D, distributed tactile sensing, and a compact 2D proximity representation. The model couples a learned, action-conditioned latent dynamics model with analytical kinematics through contact Jacobians, enabling rollouts of future contact configurations and interaction forces. TACTIC integrates these rollouts into a sampling-based MPC planner with contact-aware action sampling: contact Jacobian-based projections steer sampled action sequences toward force-modulating directions, and objectives defined over predicted proximity and interaction forces trade task progress against whole-arm force regulation. We evaluate TACTIC in simulation against state-of-the-art model-based and model-free methods, and perform ablations that isolate the contribution of each design choice. Across experiments, TACTIC consistently outperforms other methods. We further demonstrate real-world performance on a robot with distributed tactile sensing across three whole-arm manipulation tasks that require multi-contact trajectories: turning over and repositioning a manikin, and goal-reaching in a 3D dynamic maze.
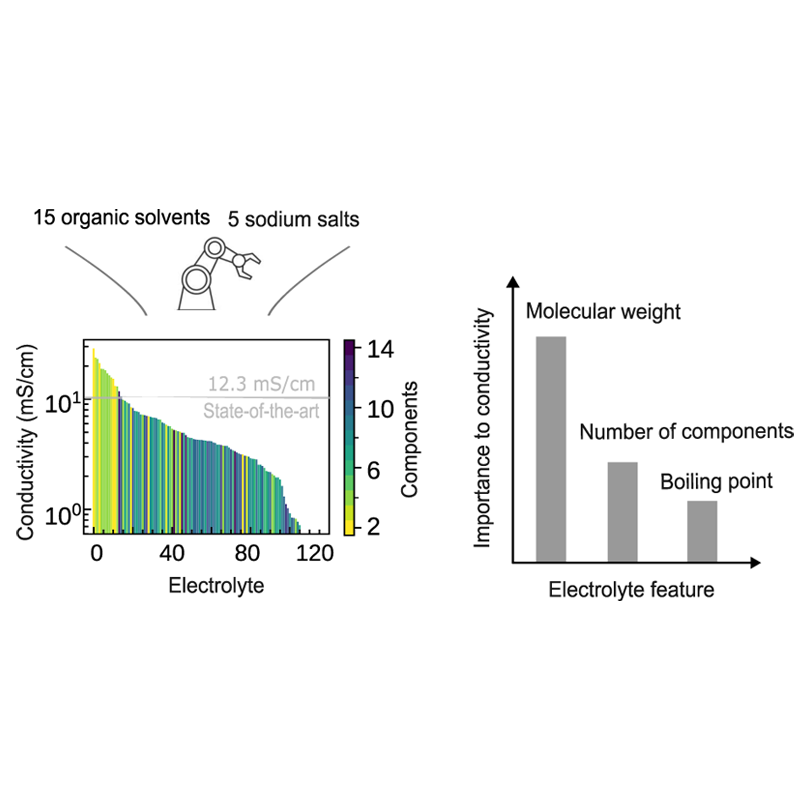
The discovery of advanced battery electrolytes is challenged by the vast compositional space of multi-component liquid formulations. Here, we introduce the ELectrolyte Laboratory for Integrated Experimentation (ELLIE), an automated platform that combines electrolyte formulation and impedance spectroscopy to map ionic conductivity across high-dimensional sodium electrolytes containing up to five salts and 15 solvents, generating an experimental dataset spanning nearly two orders of magnitude in conductivity. 23Na NMR, Raman spectroscopy, and viscosity measurements on a subset of electrolytes at a fixed salt concentration reveal that conductivity is jointly influenced by Na+ solvation strength, ion association, and solvent dynamics and positively correlates with inverse viscosity. Conductivity estimates based on the Nernst-Einstein relation captures broad concentration and viscosity relationships but do not extrapolate well across compositionally diverse electrolytes. Random forest modeling identifies lower solvent molecular weight as the dominant descriptor of high conductivity. Together, these results establish solvent molecular size as a physically interpretable descriptor of ion transport and demonstrate how automated experimentation can accelerate data-driven electrolyte optimization across complex compositional spaces.
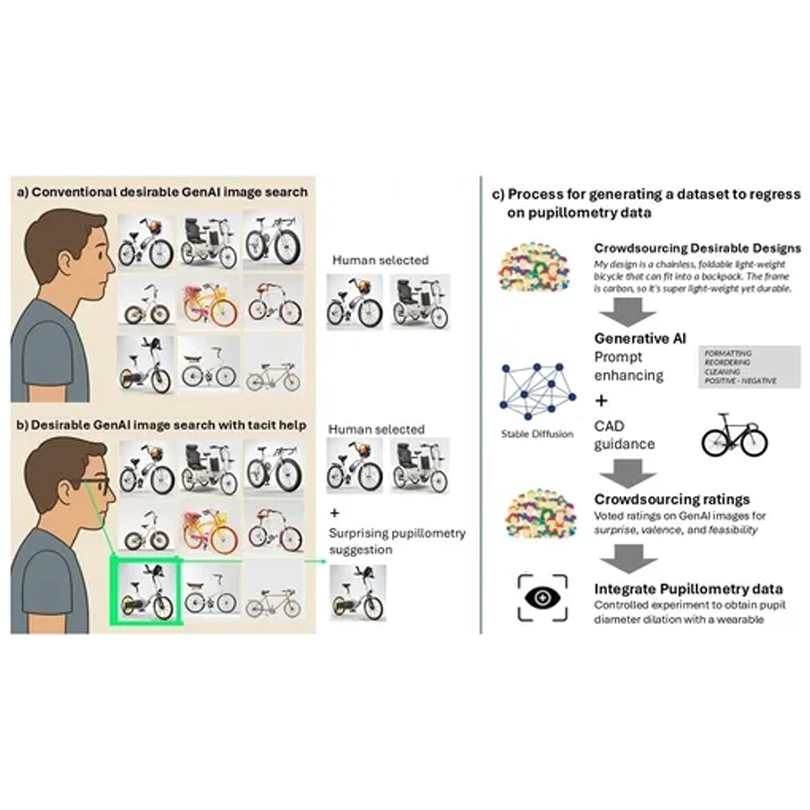
Generative AI enables designers to more broadly and rapidly explore design spaces. However, the sheer scale at which designs can be generated makes it difficult to identify which generated concepts deserve further attention. To support this identification process, we explore pupillometry—specifically pupil dilation—as a support signal for design evaluation. We conducted a study with 40 participants who viewed AI-generated bicycle designs while wearing eye tracking glasses to measure pupil dilation and rated designs on perceived surprise, valence, and feasibility.
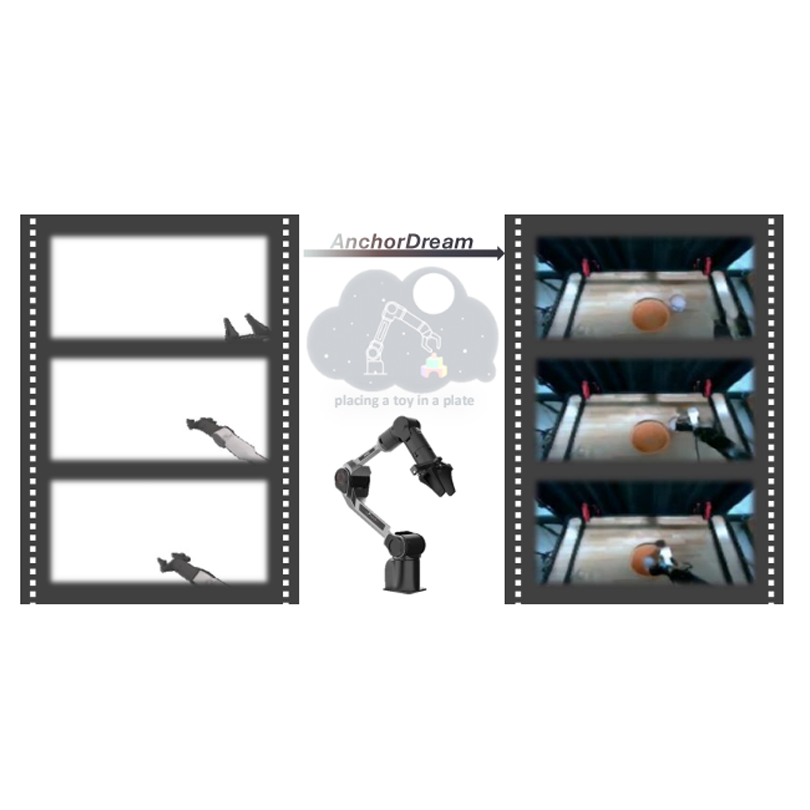
The collection of large-scale and diverse robot demonstrations remains a major bottleneck for imitation learning, as real-world data acquisition is costly and simulators offer limited diversity and fidelity with pronounced sim-to-real gaps. While generative models present an attractive solution, existing methods often alter only visual appearances without creating new behaviors, or suffer from embodiment inconsistencies that yield implausible motions. To address these limitations, we introduce AnchorDream, an embodiment-aware world model that repurposes pretrained video diffusion models for robot data synthesis. AnchorDream conditions the diffusion process on robot motion renderings, anchoring the embodiment to prevent hallucination while synthesizing objects and environments consistent with the robot's kinematics. Starting from only a handful of human teleoperation demonstrations, our method scales them into large, diverse, high-quality datasets without requiring explicit environment modeling. Experiments show that the generated data leads to consistent improvements in downstream policy learning, with relative gains of 36.4% in simulator benchmarks and nearly double performance in real-world studies. These results suggest that grounding generative world models in robot motion provides a practical path toward scaling imitation learning.
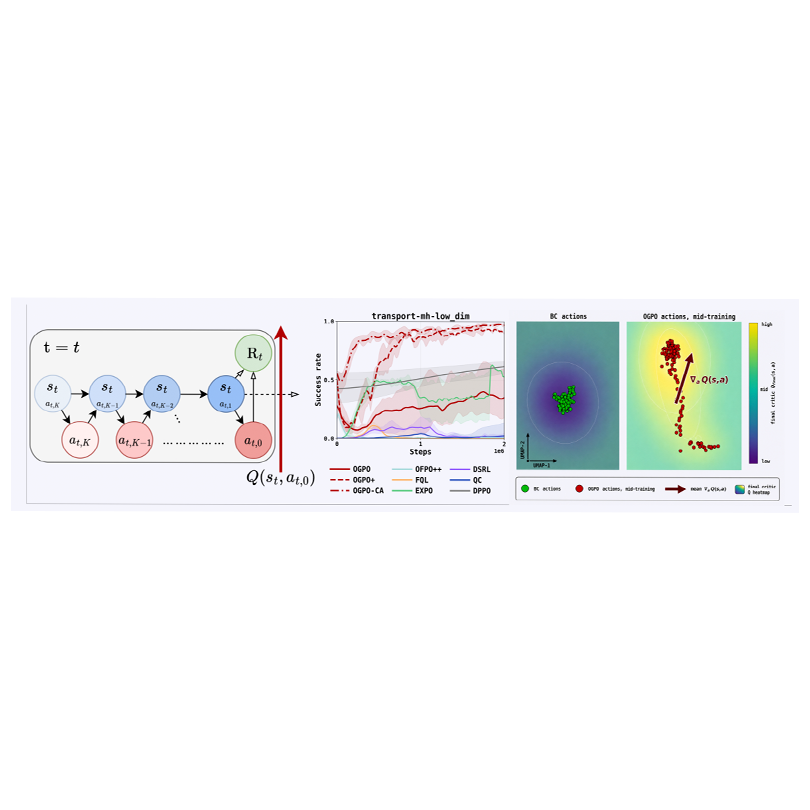
Generative control policies (GCPs), such as diffusion- and flow-based control policies, have emerged as effective parameterizations for robot learning. This work introduces Off-policy Generative Policy Optimization (OGPO), a sample-efficient algorithm for finetuning GCPs that maintains off-policy critic networks to maximize data reuse and propagate policy gradients through the full generative process of the policy via a modified PPO objective, using critics as the terminal reward. OGPO achieves state-of-the-art performance on manipulation tasks spanning multi-task settings, high-precision insertion, and dexterous control. To our knowledge, it is also the only method that can fine-tune poorly-initialized behavior cloning policies to near full task-success with no expert data in the online replay buffer, and does so with few task-specific hyperparameter tuning. Through extensive empirical investigations, we demonstrate that OGPO drastically outperforms methods alternatives on policy steering and learning residual corrections, and identify the key mechanisms behind its performance. We further introduce practical stabilization tricks, including success-buffer regularization, two-sided conservative advantages, and Q-variance reduction, to mitigate critic over-exploitation across state- and pixel-based settings. Beyond proposing OGPO, we conduct a systematic empirical study of GCP finetuning, identifying the stabilizing mechanisms and failure modes that govern successful off-policy full-policy improvement.
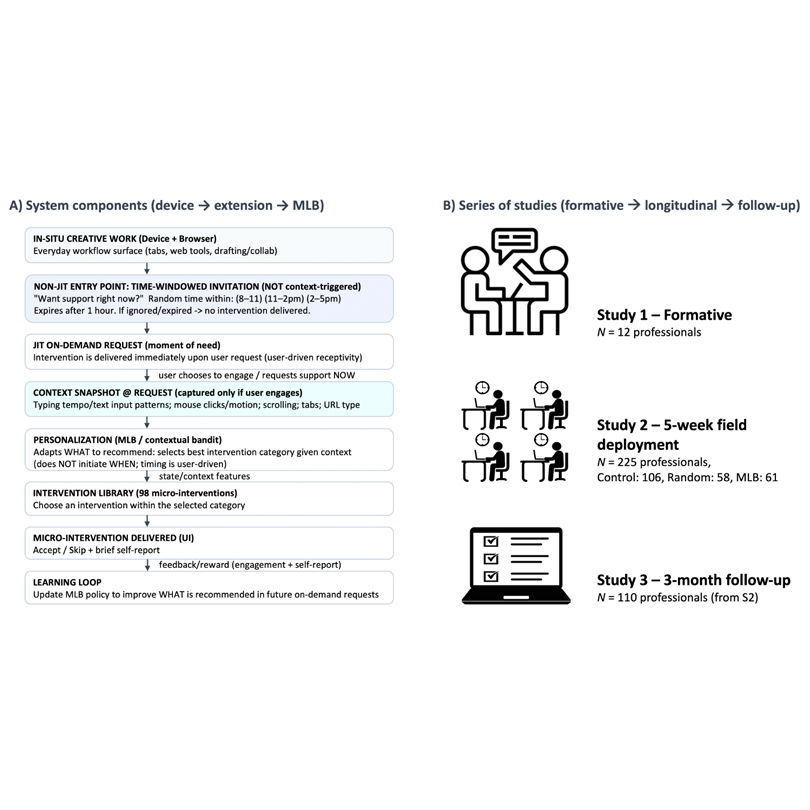
Creative professionals often experience "stuckness," moments when ideas stall, or motivation fades. We define creative stuckness as a temporary state of self-regulatory misalignment - an impasse marked by perceived obstruction of progress and dysregulation of attention, affect, and motivation. Unstuck is a ubiquitous just-in-time system that detects contextual cues of stuckness and delivers brief, autonomy-preserving micro-interventions. A formative study with twelve professionals identified these mechanisms and informed a library of 98 interventions spanning embodied, cognitive, and reflective strategies. In a five-week deployment with 225 creative professionals (106 Control, 58 Random, 61 adaptive MLB), both intervention arms improved creative self-efficacy, coping, and wellbeing and produced consistent creativity boosts. 77% reported that Unstuck helped them manage their creativity and focus. Three months later (N=110), nearly 60% continued using Unstuck-inspired strategies such as mindful resets, reframing, and movement. These findings show that short, context-aware interventions can transform transient impasses into lasting self-regulation and creative wellbeing.