Featured Publications
All Publications

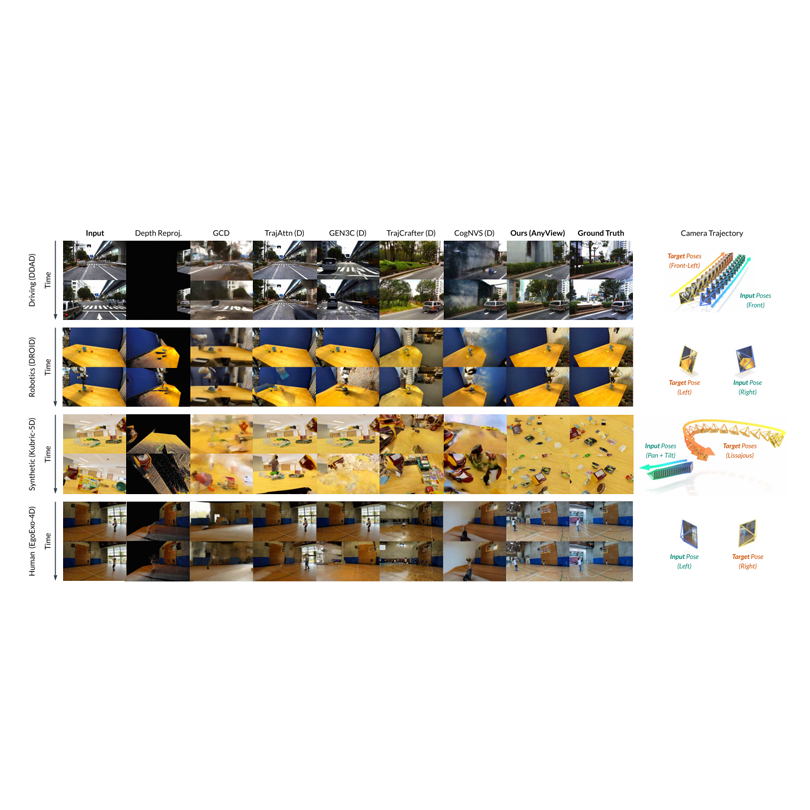
Modern generative video models excel at producing convincing, high-quality outputs, but struggle to maintain multi-view and spatiotemporal consistency in highly dynamic real-world environments. In this work, we introduce AnyView, a diffusion-based video generation framework for dynamic view synthesis with minimal inductive biases or geometric assumptions. We leverage multiple data sources with various levels of supervision, including monocular (2D), multi-view static (3D) and multi-view dynamic (4D) datasets, to train a generalist spatiotemporal implicit representation capable of producing zero-shot novel videos from arbitrary camera locations and trajectories. We evaluate AnyView on standard benchmarks, showing competitive results with the current state of the art, and propose AnyViewBench, a challenging new benchmark tailored towards extreme dynamic view synthesis in diverse real-world scenarios. In this more dramatic setting, we find that most baselines drastically degrade in performance, as they require significant overlap between viewpoints, while AnyView maintains the ability to produce realistic, plausible, and spatiotemporally consistent videos when prompted from any viewpoint.
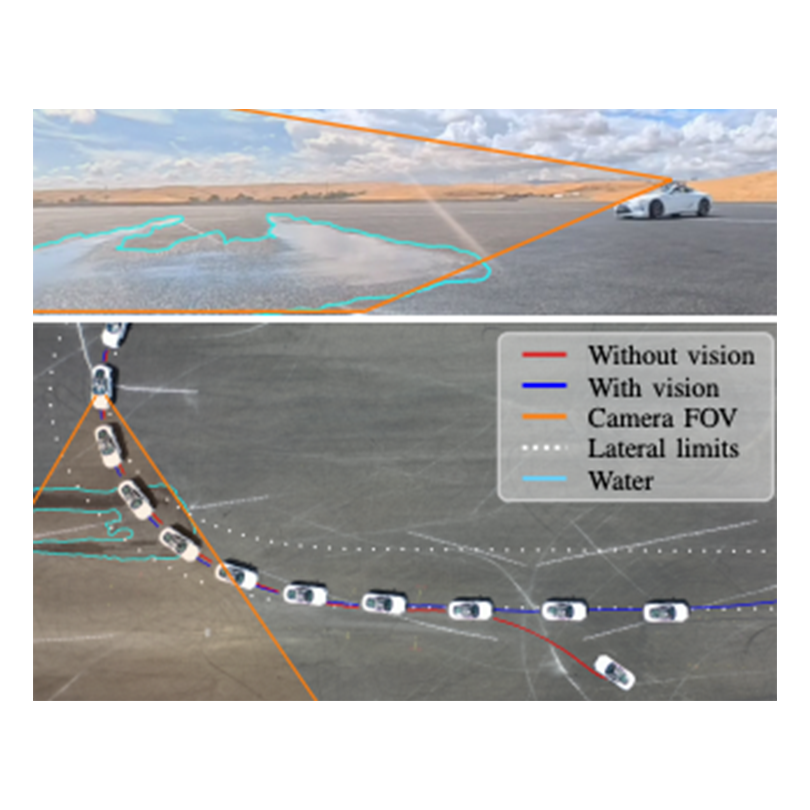
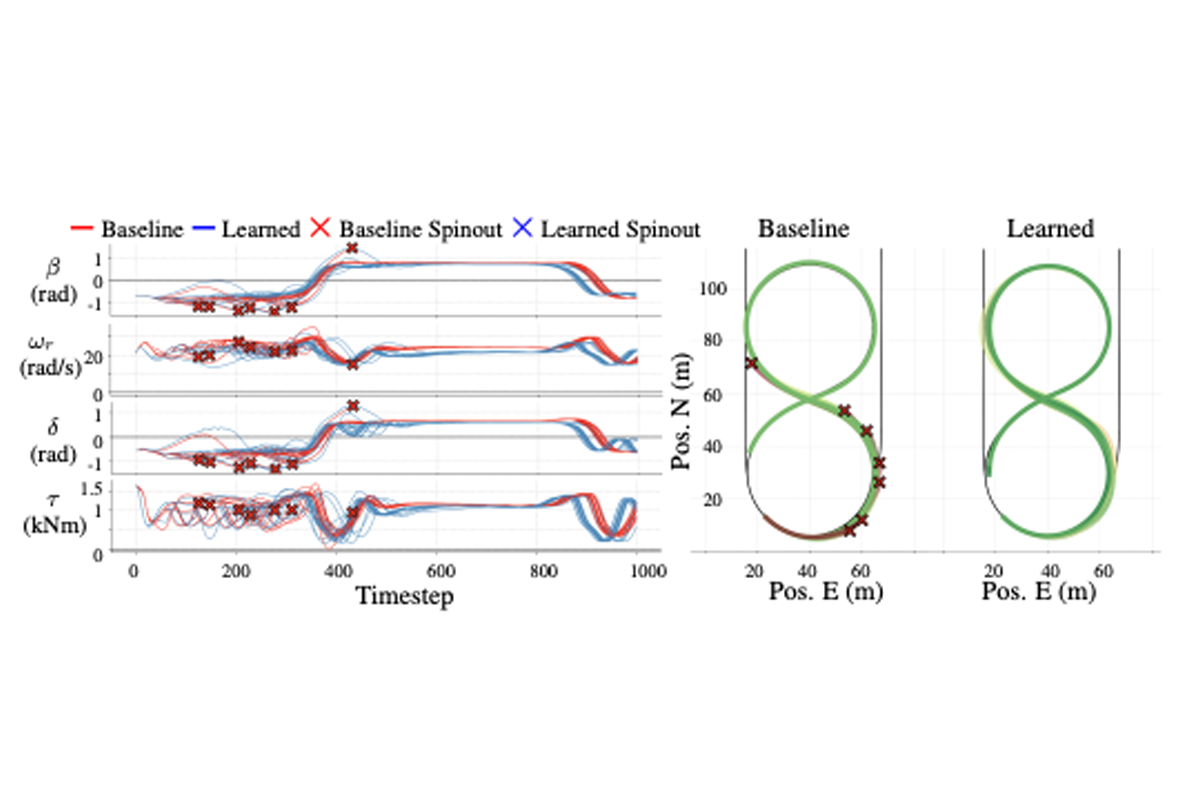
Agile control of robotic systems often requires anticipating how the environment affects system behavior. For example, a driver must perceive the road ahead to anticipate available friction and plan actions accordingly. Achieving such proactive adaptation within autonomous frameworks remains a challenge, particularly under rapidly changing conditions. Traditional modeling approaches often struggle to capture abrupt variations in system behavior, while adaptive methods are inherently reactive and may adapt too late to ensure safety. We propose a vision-conditioned variational Bayesian last-layer dynamics model that leverages visual context to anticipate changes in the environment. The model first learns nominal vehicle dynamics and is then fine-tuned with feature-wise affine transformations of latent features, enabling context-aware dynamics prediction. The resulting model is integrated into an optimal controller for vehicle racing. We validate our method on a Lexus LC500 racing through water puddles. With vision-conditioning, the system completed all 12 attempted laps under varying conditions. In contrast, all baselines without visual context consistently lost control, demonstrating the importance of proactive dynamics adaptation in high-performance applications.
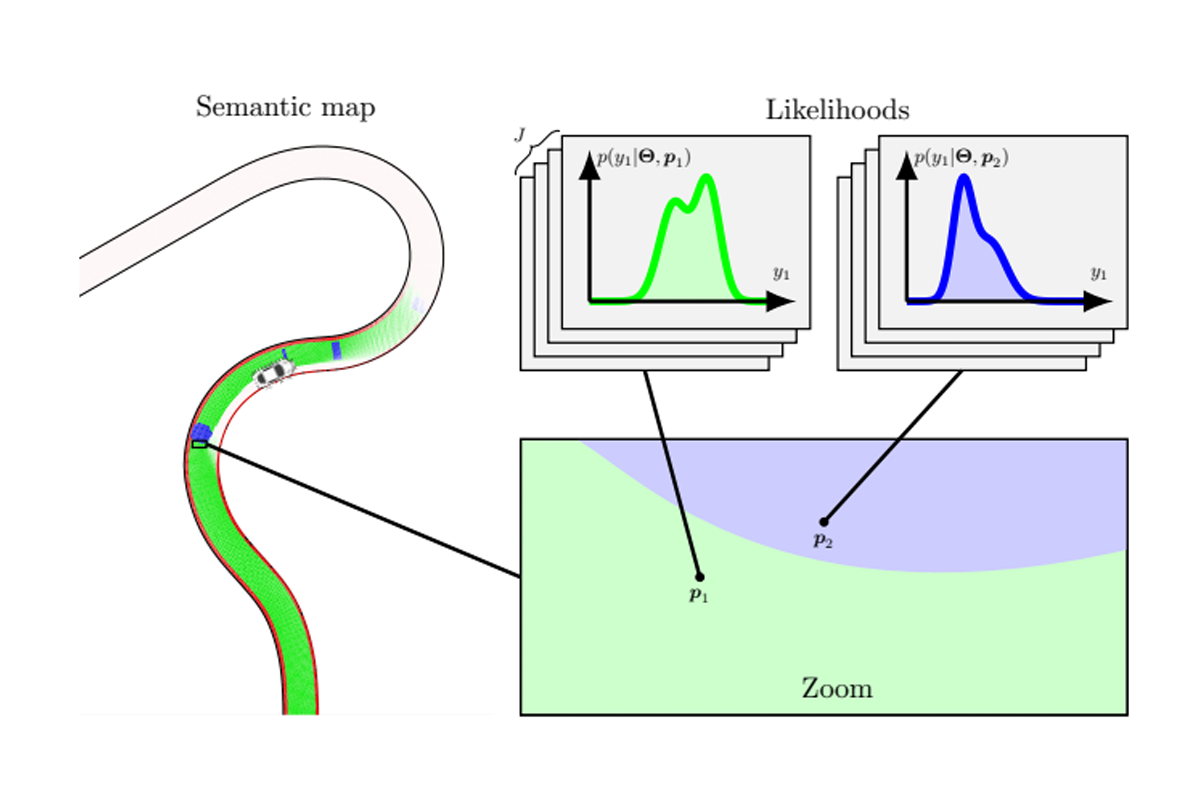
We propose a probabilistic semantic filtering framework in which parameters of a dynamical system are inferred and associated with a closed set of semantic classes in a map. We extend existing methods to a multi-parameter setting using a posterior that tightly couples semantics with the parameter likelihoods, and propose a filter to compute this posterior sequentially, subject to dynamics in the map's state. Using Bayesian moment matching, we show that the computational complexity of measurement updates scales linearly in the dimension of the parameter space. Finally, we demonstrate limitations of applying existing methods to a problem from the driving domain, and show that the proposed framework better captures time-varying parameter-to-semantic associations.
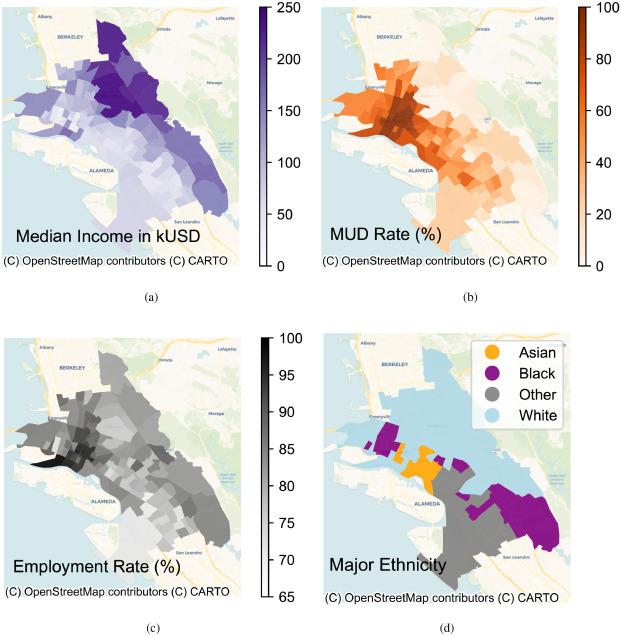
This study introduces a framework for improving accessibility to and quantifying social equity priorities in electric vehicle charging infrastructure through strategic workplace charger placement. We develop a customizable equity evaluation model that quantifies access disparities across demographic groups. This model is used to construct an optimization framework that informs charging infrastructure deployment decisions. Leveraging commuting patterns, we demonstrate in the case study of Oakland, California that strategically placing workplace charging can achieve, on average, a 1.8-fold reduction in accessible charging resource disparities compared to benchmark scenarios. Our analysis reveals that targeted workplace charger deployment in high-commuter zones can disproportionately improve citywide equity. The framework provides policymakers with quantifiable metrics to evaluate trade-offs between sometimes divergent equity considerations (e.g., income, housing type) and offers practical insights for achieving more equitable charging infrastructure distribution.
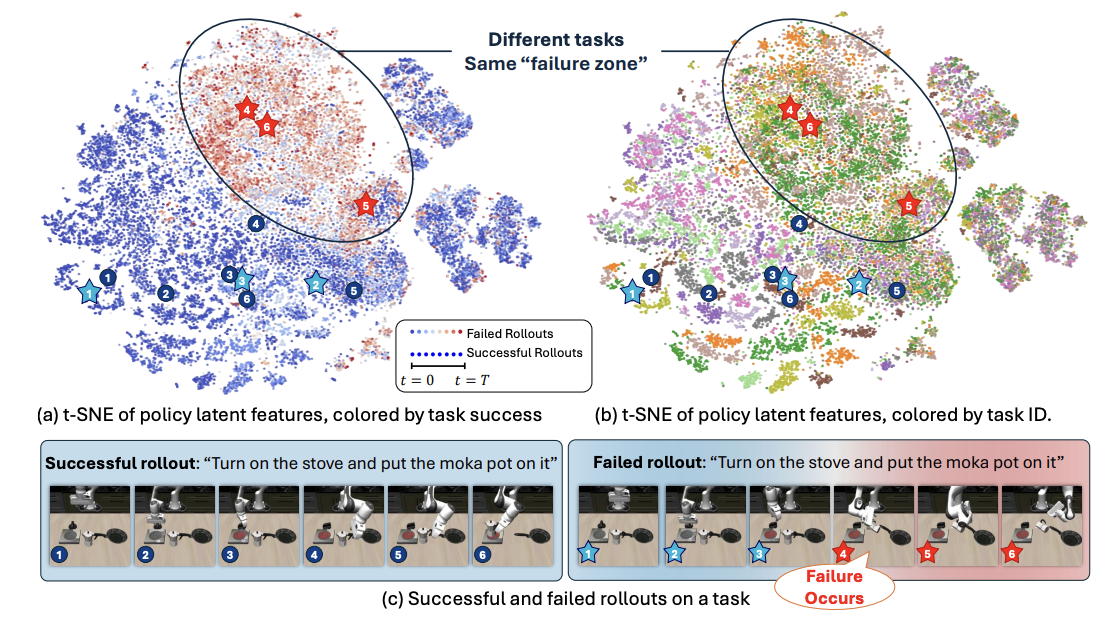
While vision-language-action models (VLAs) have shown promising robotic behaviors across a diverse set of manipulation tasks, they achieve limited success rates when deployed on novel tasks out of the box. To allow these policies to safely interact with their environments, we need a failure detector that gives a timely alert such that the robot can stop, backtrack, or ask for help. However, existing failure detectors are trained and tested only on one or a few specific tasks, while generalist VLAs require the detector to generalize and detect failures also in unseen tasks and novel environments. In this paper, we introduce the multitask failure detection problem and propose SAFE, a failure detector for generalist robot policies such as VLAs. We analyze the VLA feature space and find that VLAs have sufficient highlevel knowledge about task success and failure, which is generic across different tasks. Based on this insight, we design SAFE to learn from VLA internal features and predict a single scalar indicating the likelihood of task failure. SAFE is trained on both successful and failed rollouts, and is evaluated on unseen tasks. SAFE is compatible with different policy architectures. We test it on OpenVLA, π0, and π0-FAST in both simulated and real-world environments extensively. We compare SAFE with diverse baselines and show that SAFE achieves state-of-the-art failure detection performance and a favorable trade-off between accuracy and detection time using conformal prediction. More qualitative results and code can be found at the project webpage: https://vla-safe.github.io/.
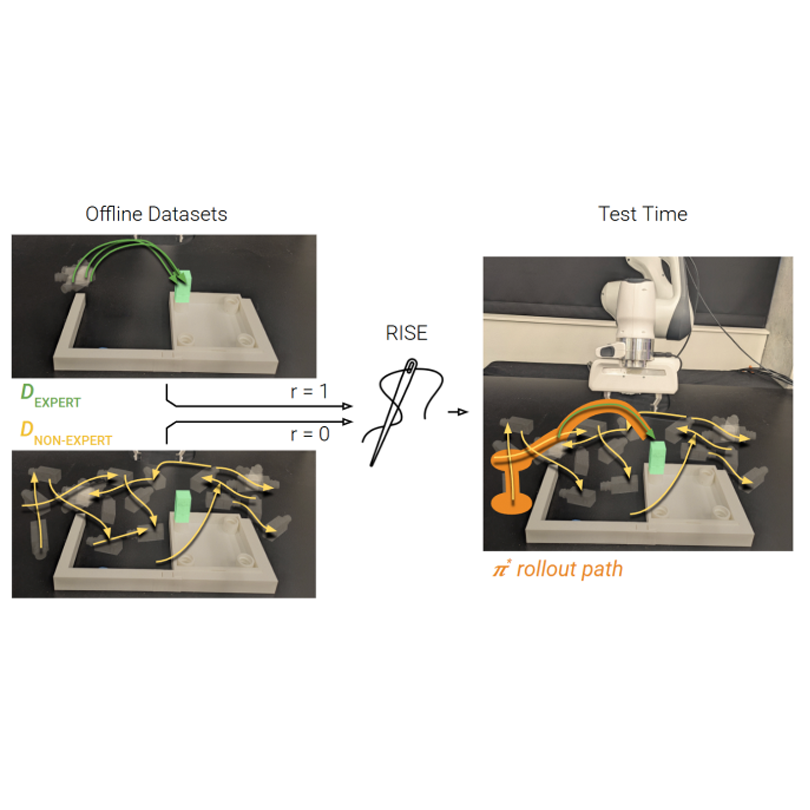
Imitation learning has proven effective for training robots to perform complex tasks from expert human demonstrations. However, it remains limited by its reliance on high-quality, task-specific data, restricting adaptability to the diverse range of real-world object configurations and scenarios. In contrast, non-expert data — such as play data, suboptimal demonstrations, partial task completions, or rollouts from suboptimal policies — can offer broader coverage and lower collection costs. However, conventional imitation learning approaches fail to utilize this data effectively. To address these challenges, we posit that with right design decisions, offline reinforcement learning can be used as a tool to harness non-expert data to enhance the performance of imitation learning policies. We show that while standard offline RL approaches can be ineffective at actually leveraging non-expert data under the sparse data coverage settings typically encountered in the real world, simple algorithmic modifications can allow for the utilization of this data, without significant additional assumptions. Our approach shows that broadening the support of the policy distribution can allow imitation algorithms augmented by offline RL to solve tasks robustly, showing considerably enhanced recovery and generalization behavior. In manipulation tasks, these innovations significantly increase the range of initial conditions where learned policies are successful when non-expert data is incorporated. Moreover, we show that these methods are able to leverage all collected data, including partial or suboptimal demonstrations, to bolster task-directed policy performance. This underscores the importance of algorithmic techniques for using non-expert data for robust policy learning in robotics.
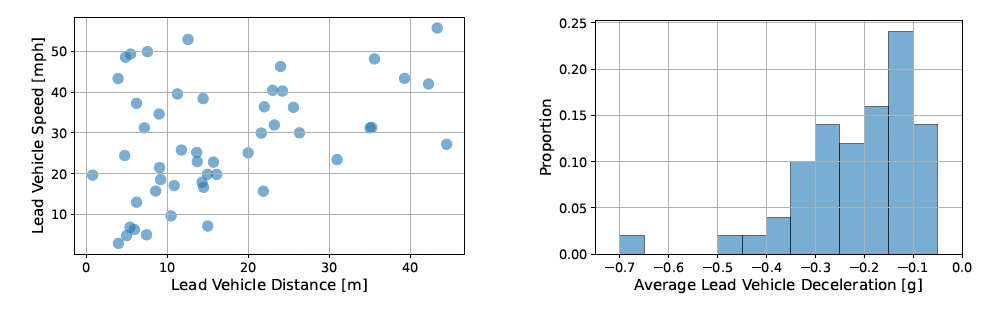
Scenarios provide a fundamental link between driving simulators and real-world conditions, shaping the extent to which the findings of a user study can be applied to public roads. However, compared to other aspects of study design, scenario development in human–vehicle interaction research tends to receive less deliberate attention. To encourage more methodical scenario generation, this work introduces a mixed methods approach for extracting representative scenarios from an integration of three real-world data sources: aggregated crash statistics, interviews with experienced drivers, and naturalistic driving data. Through a case study on winter driving, we outline the derivation of a nighttime, two-lane road scenario from these data sources and conduct an initial driving simulator pilot study to assess its realism. We hope that this demonstration of scenario generation from quantitative and qualitative data inspires researchers to consider more rigorous methods for scenario design in future work.
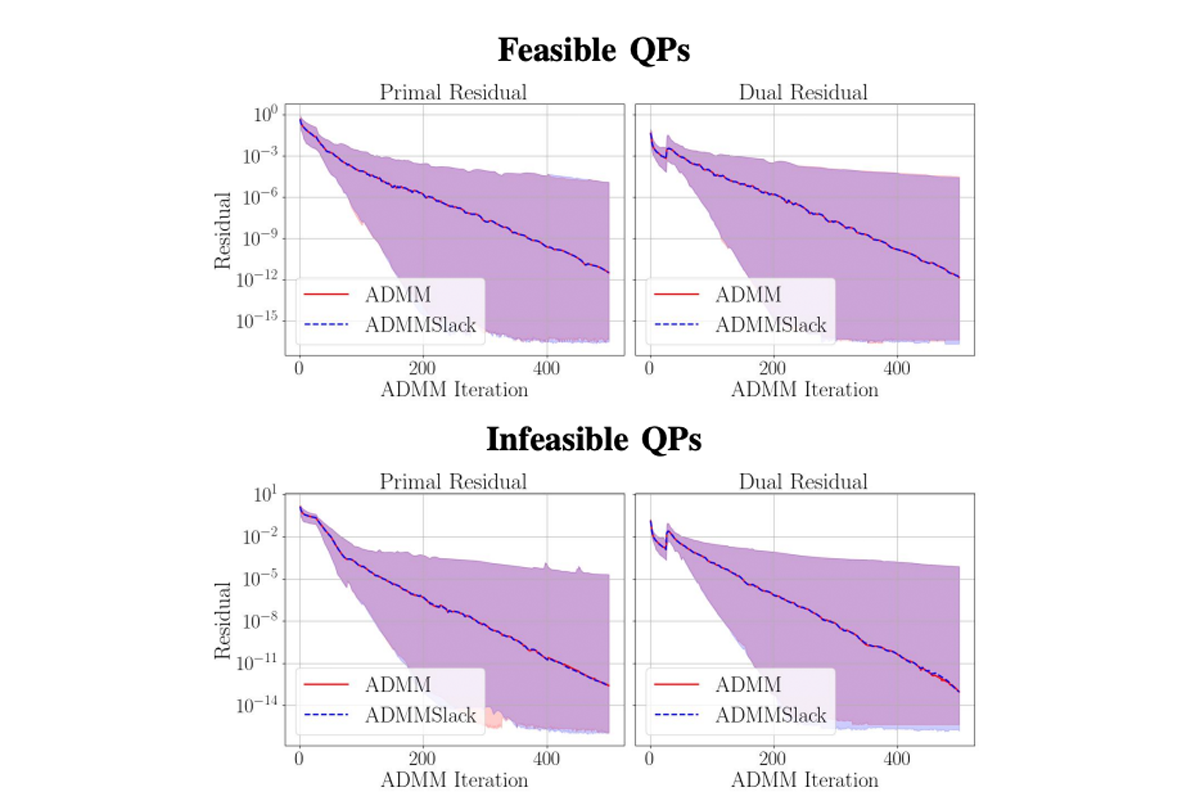
Differentiable model predictive control (MPC) offers a powerful framework for combining learning and control. However, its adoption has been limited by the inherently sequential nature of traditional optimization algorithms, which are challenging to parallelize on modern computing hardware like GPUs. In this work, we tackle this bottleneck by introducing a GPU-accelerated differentiable optimization tool for MPC. This solver leverages sequential quadratic programming and a custom preconditioned conjugate gradient (PCG) routine with tridiagonal preconditioning to exploit the problem's structure and enable efficient parallelization. We demonstrate substantial speedups over CPU- and GPU-based baselines, significantly improving upon state-of-the-art training times on benchmark reinforcement learning and imitation learning tasks. Finally, we showcase the method on the challenging task of reinforcement learning for driving at the limits of handling, where it enables robust drifting of a Toyota Supra through water puddles.
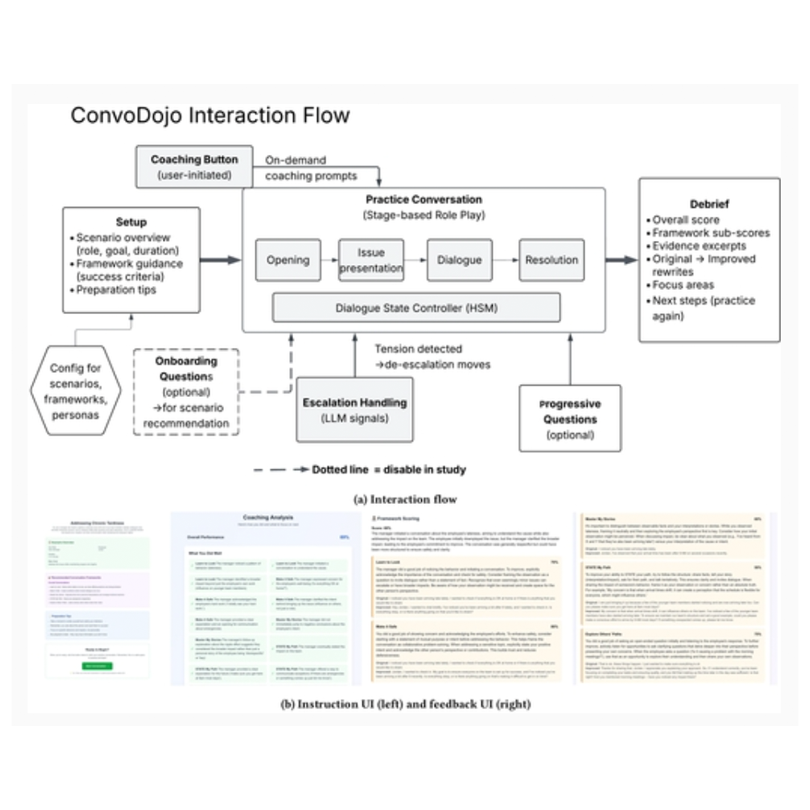
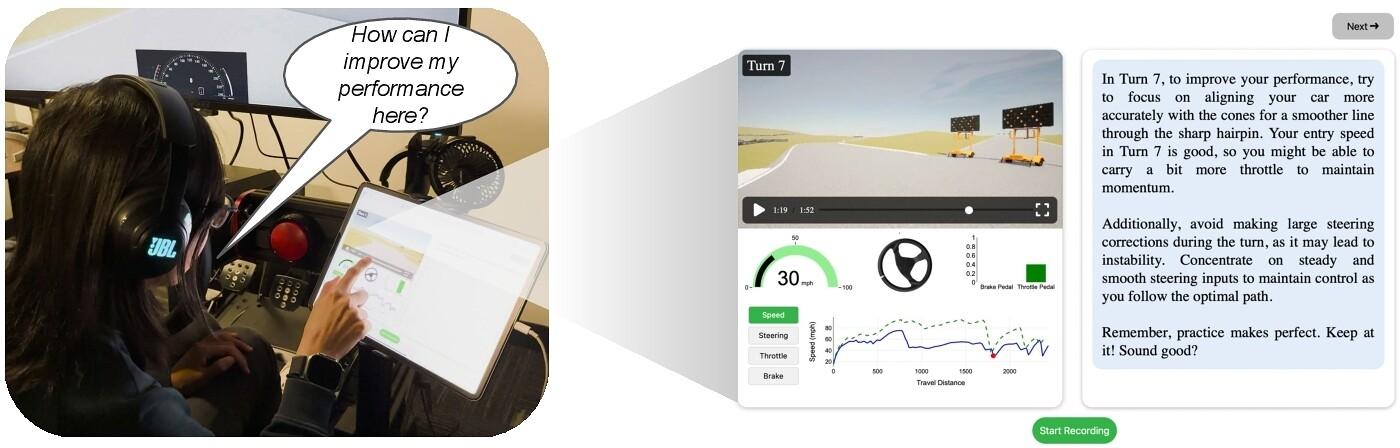
Learning in domains involving complex motor skills, such as performance driving, often requires feedback that is timely, personalized, and actionable. Yet many drivers rely on video and telemetry data to review their performance without guidance. We explore how conversational AI can support post-drive reflection by integrating LLM-generated coaching into an interactive review interface. In an exploratory within-subjects simulator study (n=16), participants completed laps under two conditions: one with video and data visualizations alone, and another with the same tools augmented with a conversational interface that provided verbal feedback after each lap. Conversational feedback supported short-term improvements in lap time, average speed, and steering control, and was rated as more useful and satisfying—though it also elicited slightly higher nervousness. These results suggest that conversational AI can make post-drive feedback more interpretable and actionable, particularly for drivers reviewing performance data in high-skill contexts like performance driving.
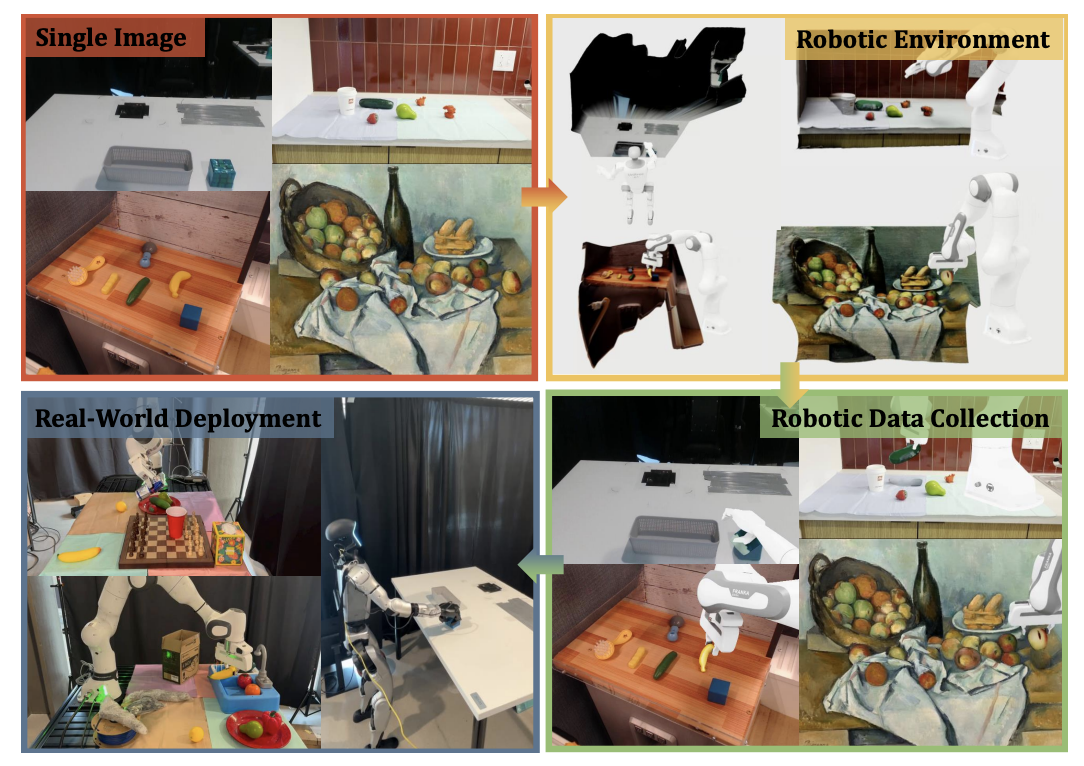
We introduce RoLA, a framework that transforms any in-the-wild image into an interactive, physics-enabled robotic environment. Unlike previous methods, RoLA operates directly on a single image without requiring additional hardware or digital assets. Our framework democratizes robotic data generation by producing massive visuomotor robotic demonstrations within minutes from a wide range of image sources, including camera captures, robotic datasets, and Internet images. At its core, our approach combines a novel method for single-view physical scene recovery with an efficient visual blending strategy for photorealistic data collection. We demonstrate RoLA's versatility across applications like scalable robotic data generation and augmentation, robot learning from Internet images, and single-image real-to-sim-to-real systems for manipulators and humanoids. Video results are available at this https URL.