Featured Publications
All Publications

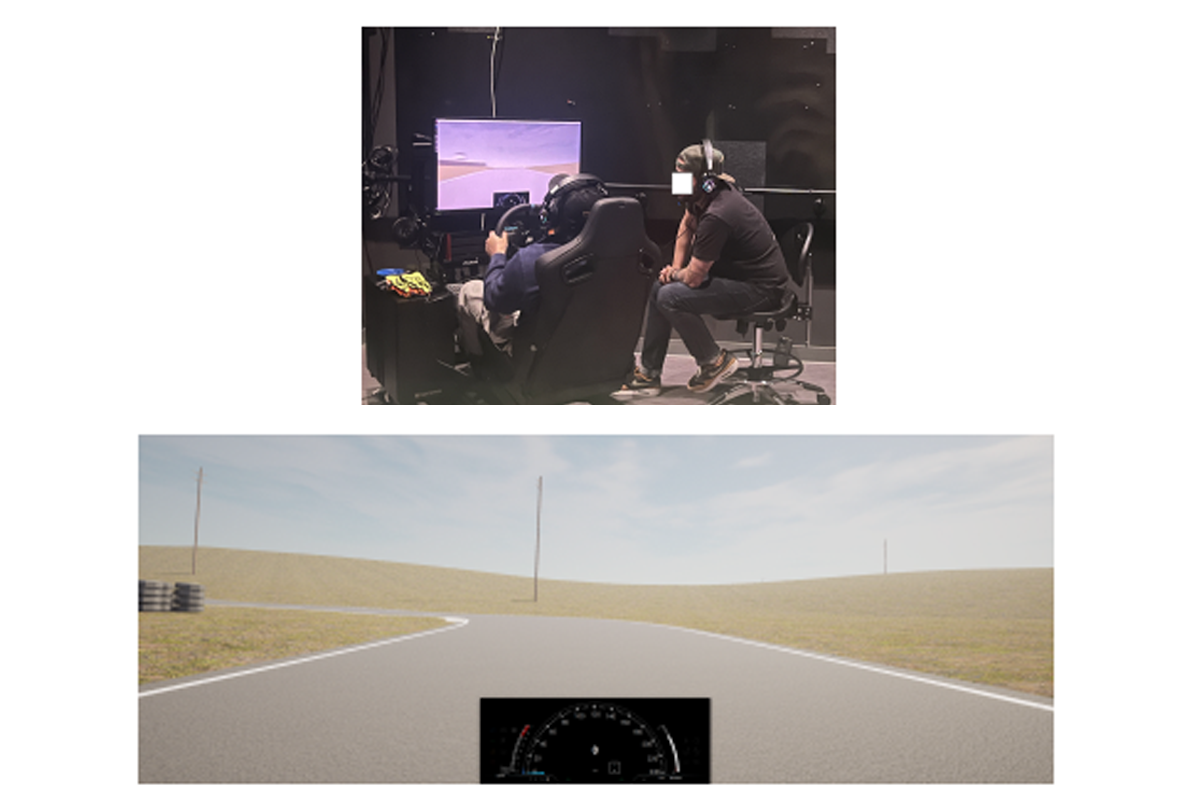
Curated datasets are essential for training and evaluating AI approaches, but are often lacking in domains where language and physical action are deeply intertwined. In particular, few datasets capture how people acquire embodied skills through verbal instruction over time. To address this gap, we introduce SIMCOACHCORPUS: a unique dataset of race car simulator driving that allows for the investigation of rich interactive phenomena during guided and unguided motor skill acquisition. In this dataset, 29 humans were asked to drive in a simulator around a race track for approximately ninety minutes. Fifteen participants were given personalized one-on-one instruction from a professional performance driving coach, and 14 participants drove without coaching. SIMCOACHCORPUS includes embodied features such as vehicle state and inputs, map (track boundaries and raceline), and cone landmarks. These are synchronized with concurrent verbal coaching from a professional coach and additional feedback at the end of each lap. We further provide annotations of coaching categories for each concurrent feedback utterance, ratings on students' compliance with coaching advice, and self-reported cognitive load and emotional state of participants (gathered from surveys during the study). The dataset includes over 20,000 concurrent feedback utterances, over 400 terminal feedback utterances, and over 40 hours of vehicle driving data. Our naturalistic dataset can be used for investigating motor learning dynamics, exploring linguistic phenomena, and training computational models of teaching. We demonstrate applications of this dataset for in-context learning, imitation learning, and topic modeling.
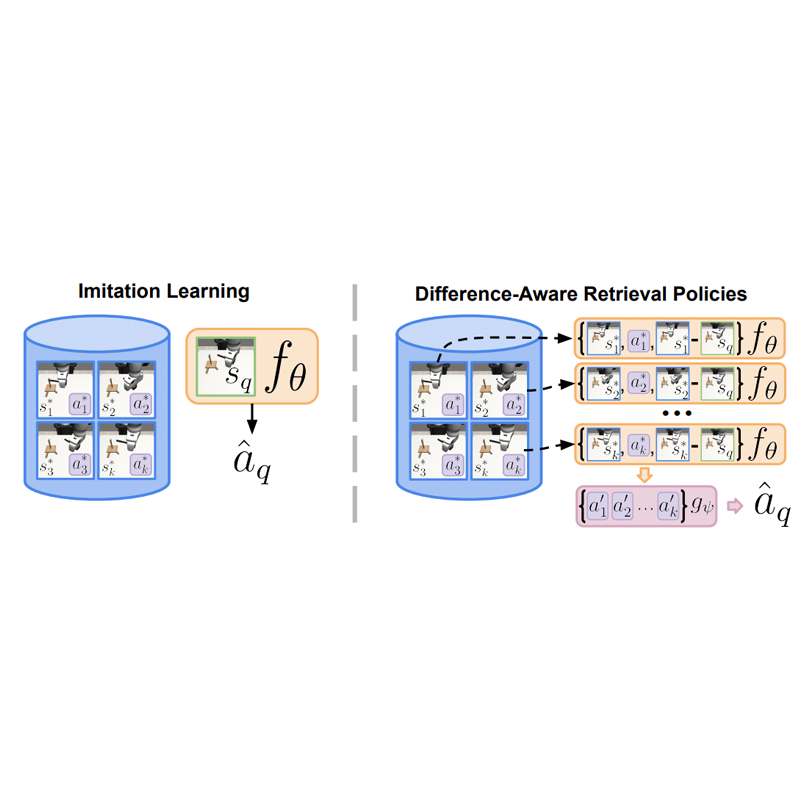
Parametric imitation learning via behavior cloning can suffer from poor generalization to out-of-distribution states due to compounding errors during deployment. We show that reusing the training data during inference via a semi-parametric retrieval-based imitation learning approach can alleviate this challenge. We present Difference-Aware Retrieval Policies for Imitation Learning (DARP), a semi-parametric retrieval-based imitation learning approach that addresses this limitation by reparameterizing the imitation learning problem in terms of local neighborhood structure rather than direct state-to-action mappings. Instead of learning a global policy, DARP trains a model to predict actions based on k-nearest neighbors from expert demonstrations, their corresponding actions, and the relative distance vectors between neighbor states and query states. DARP requires no additional assumptions beyond those made for standard behavior cloning – it does not require additional data collection, online expert feedback, or task-specific knowledge. We demonstrate consistent performance improvements of 15-46% over standard behavior cloning across diverse domains, including continuous control and robotic manipulation, and across different representations, including high-dimensional visual features.
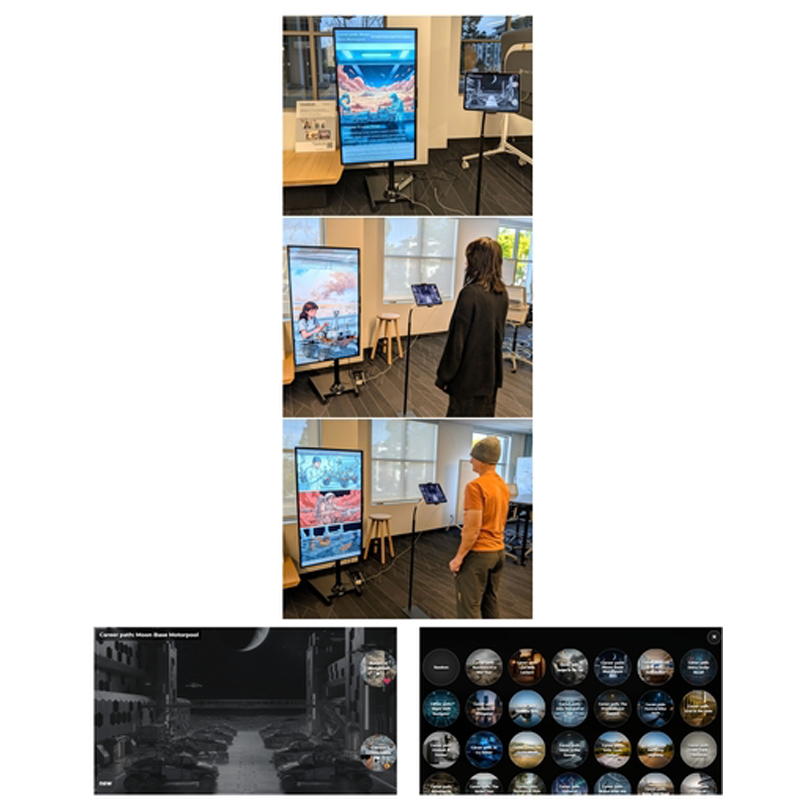
Storybook Futures is a public interactive-media installation for exploring speculative narratives. Inspired by Storybook, a web platform for creating illustrated stories that support perspective-taking and career reflection, Storybook Futures is a walk-up kiosk in which people can see themselves in a possible future. A tablet-sized controller lets participants choose among dozens of seeded paths and then branch through an illustrated story by selecting between two deliberately value-laden futures: one oriented toward well-being and one oriented toward career and financial advancement. A synchronized large display shows each chapter at audience scale, while a webcam-driven self-insertion pipeline regenerates the current scene using the participant’s face. The result is a walk-up demo that combines branching narrative and generative text and imagery that inspires questions of people’s place in the world, surveillance, and the role of AI in both. We position the system as both a narrative experience and a conversation prompt about perspective-taking, labor futures, and the politics of interactive media.
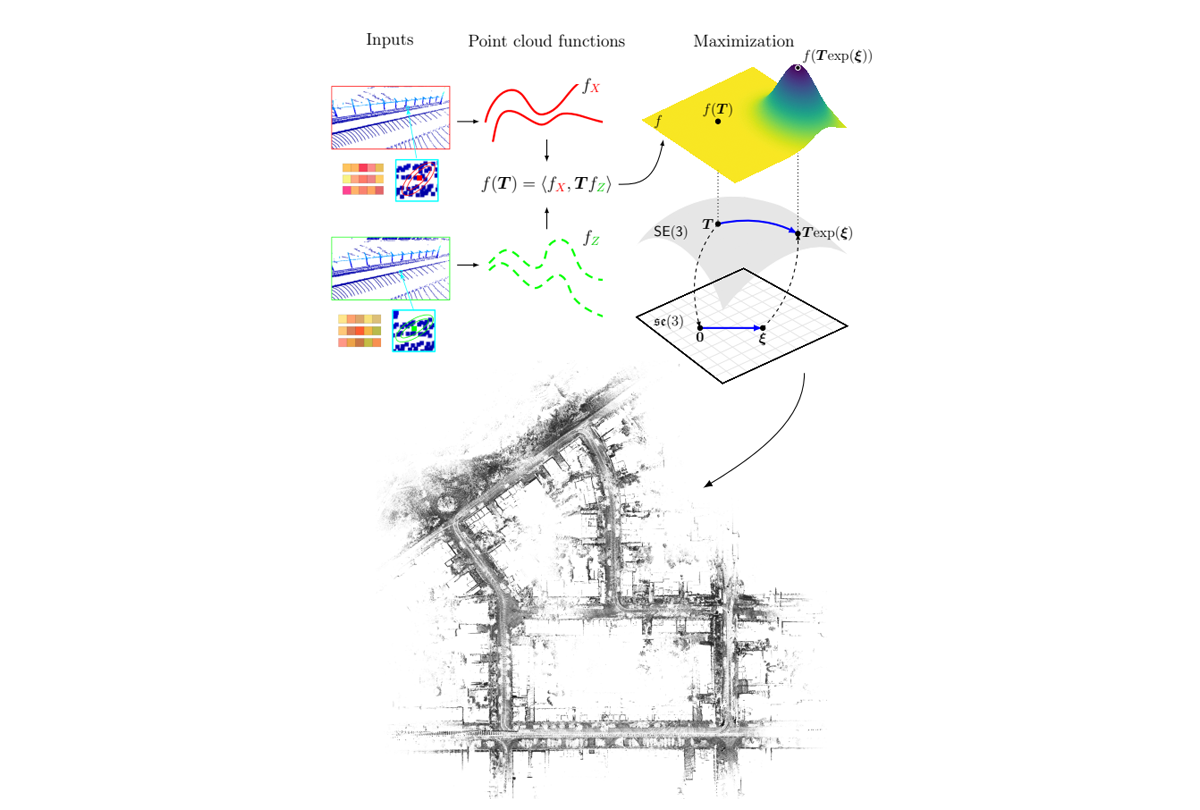
We propose a fast and correspondence-free local point cloud registration method that leverages geometric surface structure and reproducing kernel Hilbert space (RKHS) embeddings. The method represents point clouds as continuous functions with point-wise anisotropic kernels that encode local geometry. This formulation improves alignment along surface normals while relaxing alignment along tangential directions. To solve the resulting registration problem, we propose a second-order on-manifold optimization scheme with approximate Riemannian Hessians, achieving a speedup of up to 10x over the first-order solvers used in prior correspondence-free RKHS-based methods. We demonstrate improved frame-to-frame LiDAR and RGB-D tracking accuracy across diverse indoor and outdoor datasets. On a LiDAR tracking registration task in the driving domain, we achieve a reduction of > 55% in both translational and rotational drift in challenging feature-sparse environments. On object registration benchmarks, we show improved robustness over ICP-based methods and further gains when refining global initialization, particularly under moderate misalignment.
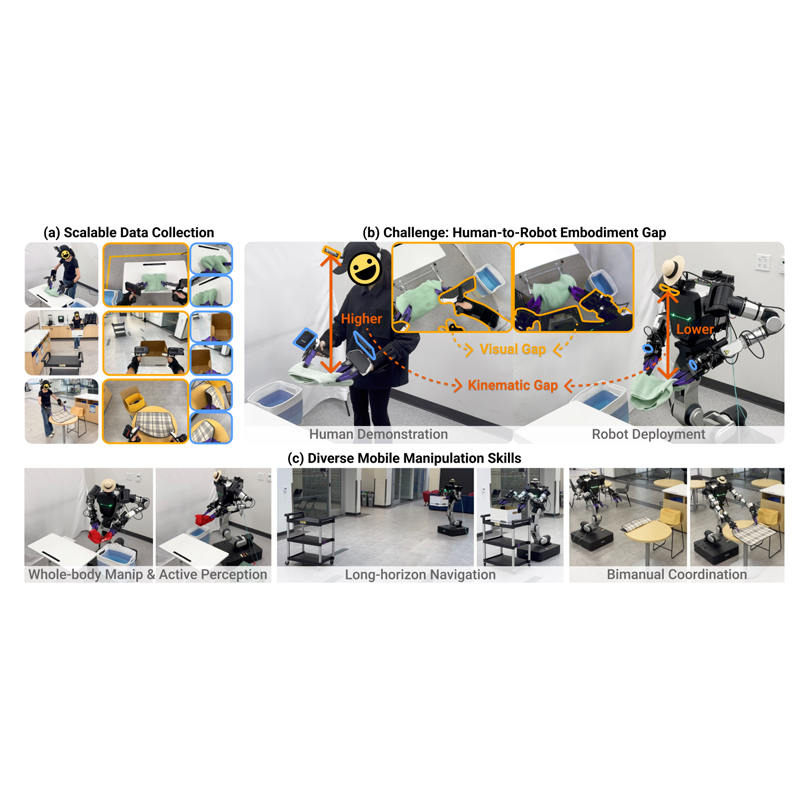
We present Whole-Body Mobile Manipulation Interface (HoMMI), a data collection and policy learning framework that learns whole-body mobile manipulation directly from robot-free human demonstrations. We augment UMI interfaces with egocentric sensing to capture the global context required for mobile manipulation, enabling portable, robot-free, and scalable data collection. However, naively incorporating egocentric sensing introduces a larger human-to-robot embodiment gap in both observation and action spaces, making policy transfer difficult. We explicitly bridge this gap with a cross-embodiment hand-eye policy design, including an embodiment agnostic visual representation; a relaxed head action representation; and a whole-body controller that realizes hand-eye trajectories through coordinated whole-body motion under robot-specific physical constraints. Together, these enable long-horizon mobile manipulation tasks requiring bimanual and whole-body coordination, navigation, and active perception.
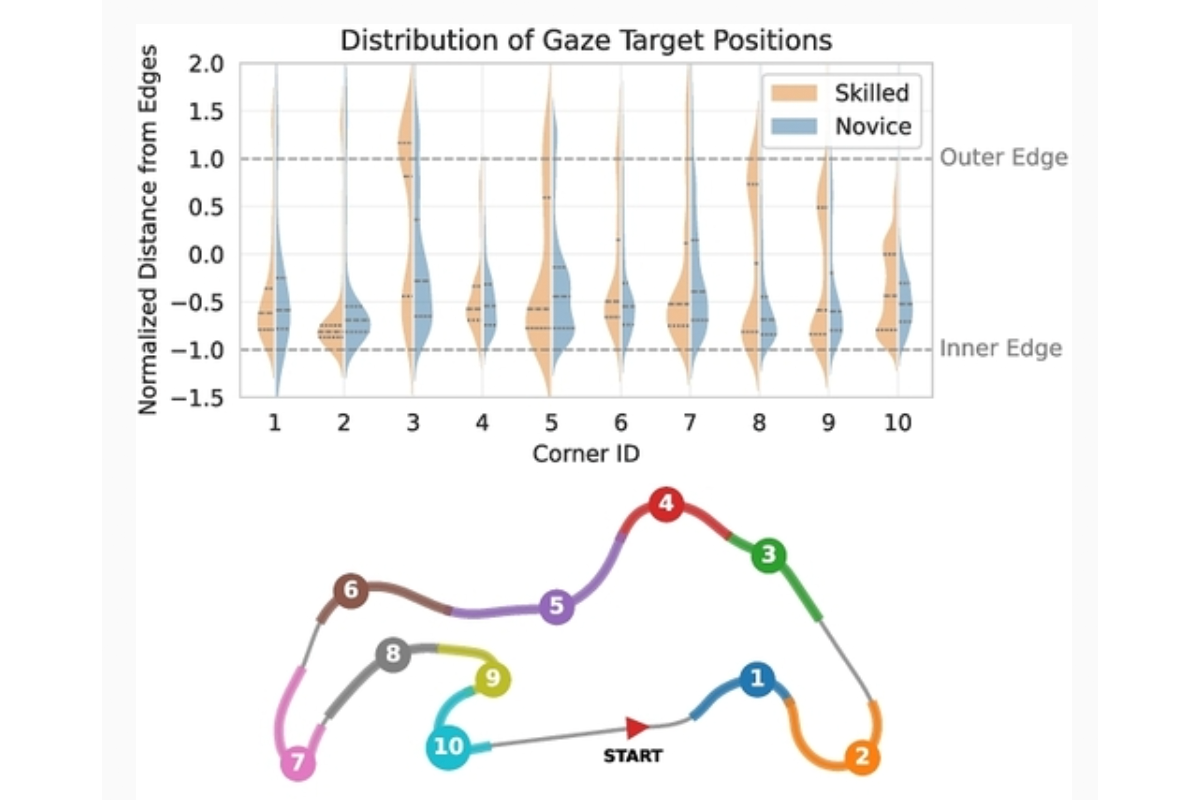
Gaze behavior is widely treated as a trainable component of high-performance driving, yet its causal role in performance remains unclear. We tested whether enforcing expert gaze patterns improves circuit driving performance in a simulator study with 60 participants assigned to free gaze, skilled-gaze guidance, or novice-gaze guidance. Gaze guidance replayed naturalistic gaze trajectories from actual skilled and novice drivers during training, followed by an unguided retention session. Despite clear compliance with gaze instructions during training, gaze guidance had no significant effect on lap time, steering or pedal smoothness, or lateral deviation from an optimal racing line, aside from a minimal per-corner difference. Performance improvements were attributable to practice and persisted independently of gaze condition. These findings suggest that gaze guidance alone is insufficient to improve high-performance driving, underscoring the need for training approaches that integrate it with additional instruction or feedback.
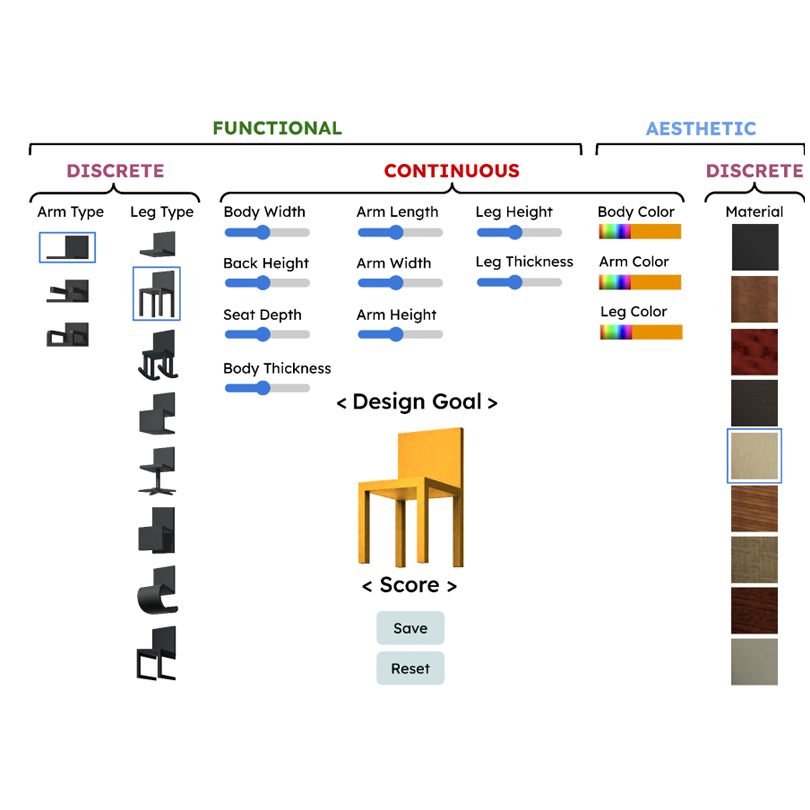
The creative design process involves transforming abstract goals into concrete outcomes through a series of decisions made under constraints. While such processes are commonly shaped by feedback like rewards, their impact on design decision making remains unclear. To better understand the role of rewards in the design process, we modeled a 3D parametric, goal-based chair design task as a Markov Decision Process. We tracked participants' decisions as they iteratively developed designs for an abstract design goal, and presented either a goal-aligned or goal-agnostic reward at every step. We tested the effect of these rewards on task behaviour and self-reported experience. With rewards, participants more thoroughly explored the design space, and maximised goal-aligned over goal-agnostic rewards while preserving diversity across designs. The nature of the goal also mattered, influencing participants' perception of the reward's usefulness. Building on these insights, we propose guidelines for designing effective feedback for design decision making.
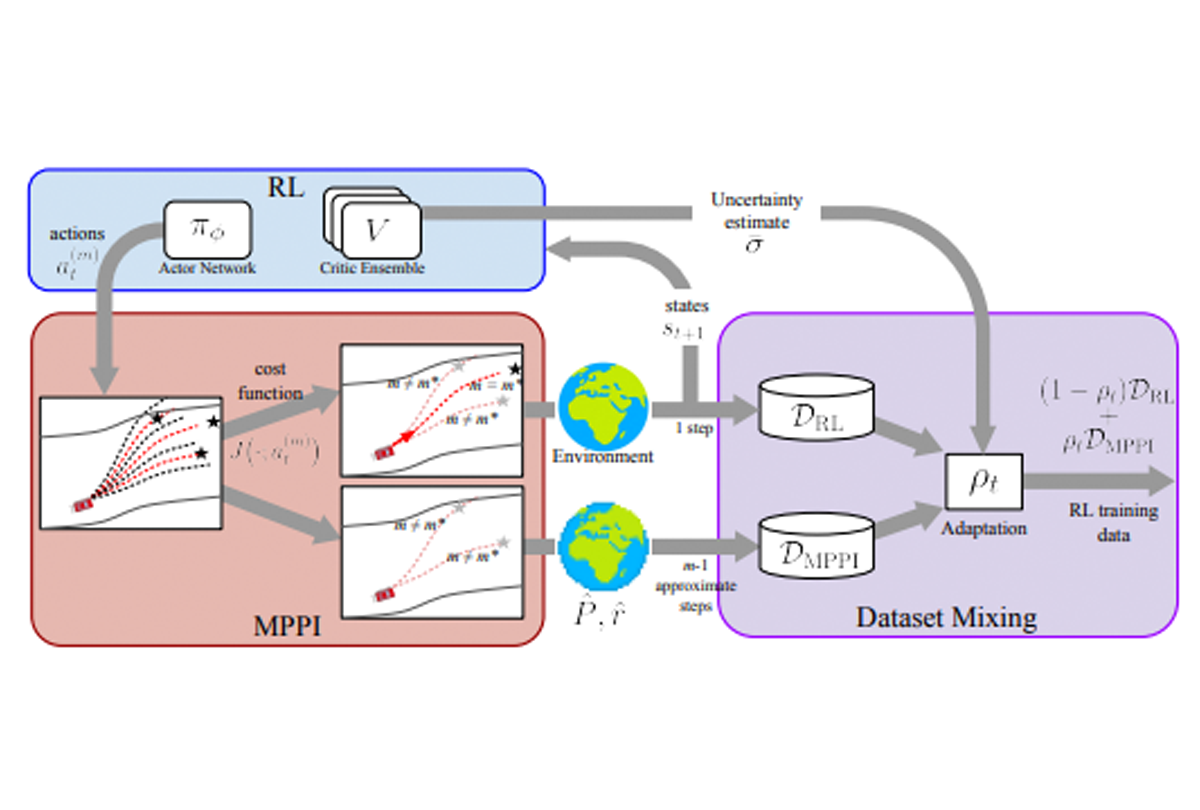
We propose a new approach for solving planning problems with a hierarchical structure, fusing reinforcement learning and MPC planning. Our formulation tightly and elegantly couples the two planning paradigms. It leverages reinforcement learning actions to inform the MPPI sampler, and adaptively aggregates MPPI samples to inform the value estimation. The resulting adaptive process leverages further MPPI exploration where value estimates are uncertain, and improves training robustness and the overall resulting policies. This results in a robust planning approach that can handle complex planning problems and easily adapts to different applications, as demonstrated over several domains, including race driving, modified Acrobot, and Lunar Lander with added obstacles. Our results in these domains show better data efficiency and overall performance in terms of both rewards and task success, with up to a 72% increase in success rate compared to existing approaches, as well as accelerated convergence (x2.1) compared to non-adaptive sampling.
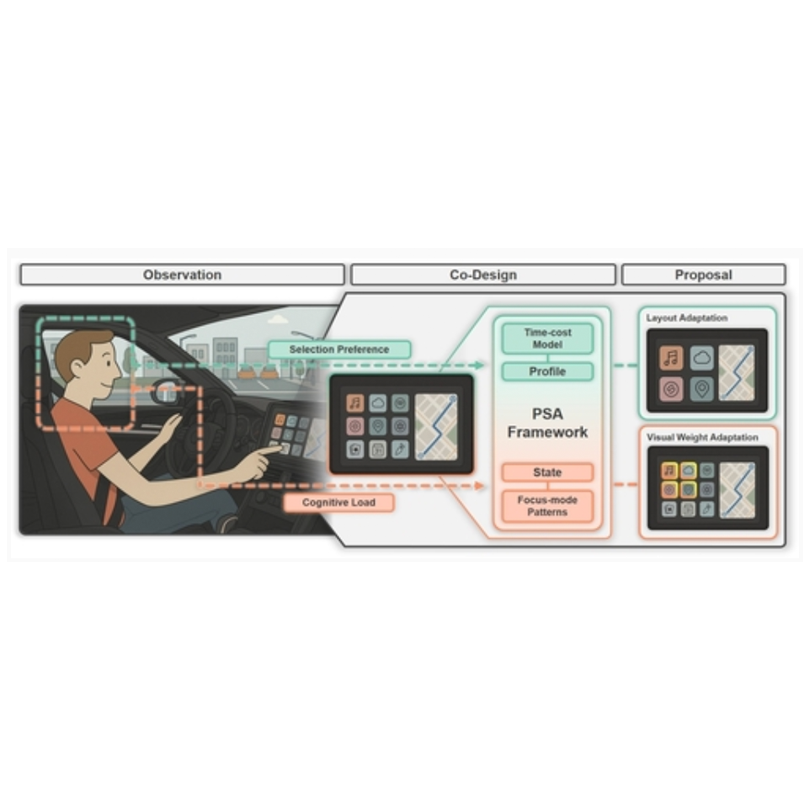
Although in-car touchscreens expand interaction possibilities, they risk compromising driver safety and vigilance. We propose a data- and expert-informed framework for designing adaptive touchscreens that respond to a driver’s usage profile and cognitive state, maximizing usability while mitigating safety risks. First, in a driving simulator study, we find that cognitive load slows touchscreen button selections by 20% and produced shorter, more frequent off-road glances. We also find that enlarging buttons improves selection speeds by 0.3 seconds but at the cost of requiring more display pages. Next, these findings informed a co-design session with expert in-cabin designers, generating guidelines for adaptive interfaces that balance usability and safety. These guidelines form the basis of our Profile-State Adaptive (PSA) framework, which integrates driver profiles with cognitive states to guide interface adaptations. We then extend the framework to include a quantitative Time-Cost model as well as design patterns for adaptive layouts across usage profiles and cognitive demands.
Effective coaching requires instruction to be tailored to each student’s skill level. While prior work has shown the importance of adaptive feedback, there is little quantitative evidence showing how coaching language itself changes as a function of skill level - particularly in real-time embodied domains. To address this gap, we collected a naturalistic dataset of an expert coach providing verbal instructions to students of varying skill in a high-performance driving simulation. Using linguistic and interaction measures, we show that, as skill improves, coaching language shifts from concrete, instructional feedback, towards evaluative and affective language. At the same time, while overall feedback amount decreases, language diversity increases, indicating a move toward denser, more expressive communication. Together, these findings provide us with a better understanding of how a human coach modulates language as a function of learner skill and provide empirical grounding for the design of adaptive and personalized AI coaching systems.