Featured Publications
All Publications

GMP-Featurizer is a lightweight, accurate, efficient, and scalable software package for calculating the Gaussian Multipole (GMP) features (Lei & Medford, 2022) for a variety of atomic systems with elements across the periodic table. Starting from the GMP feature computation module from AmpTorch (AMPTorch, 2020), the capability of GMP-Featurizer has since been greatly improved, including its accuracy and efficiency (please refer to the Overview section for details), as well as the ability to parallelize on different cores, even machines. Moreover, this Python package only has very few dependencies that are all standard Python libraries, plus CFFI for C++ code interfacing and Ray (Moritz et al., 2018) for parallelization, making it lightweight and robust. A set of unit tests are designed to ensure the reliability of its outputs. A set of extensive examples and tutorials, as well as two sets of pseudopotential files (needed for specifying the GMP feature set), are also included in this package for its users. Overall, this package is designed to serve as a standard implementation for chemical and material scientists who are interested in developing models based on GMP features. The source code for this package is freely available to the public under the Apache 2.0 license. READ MORE
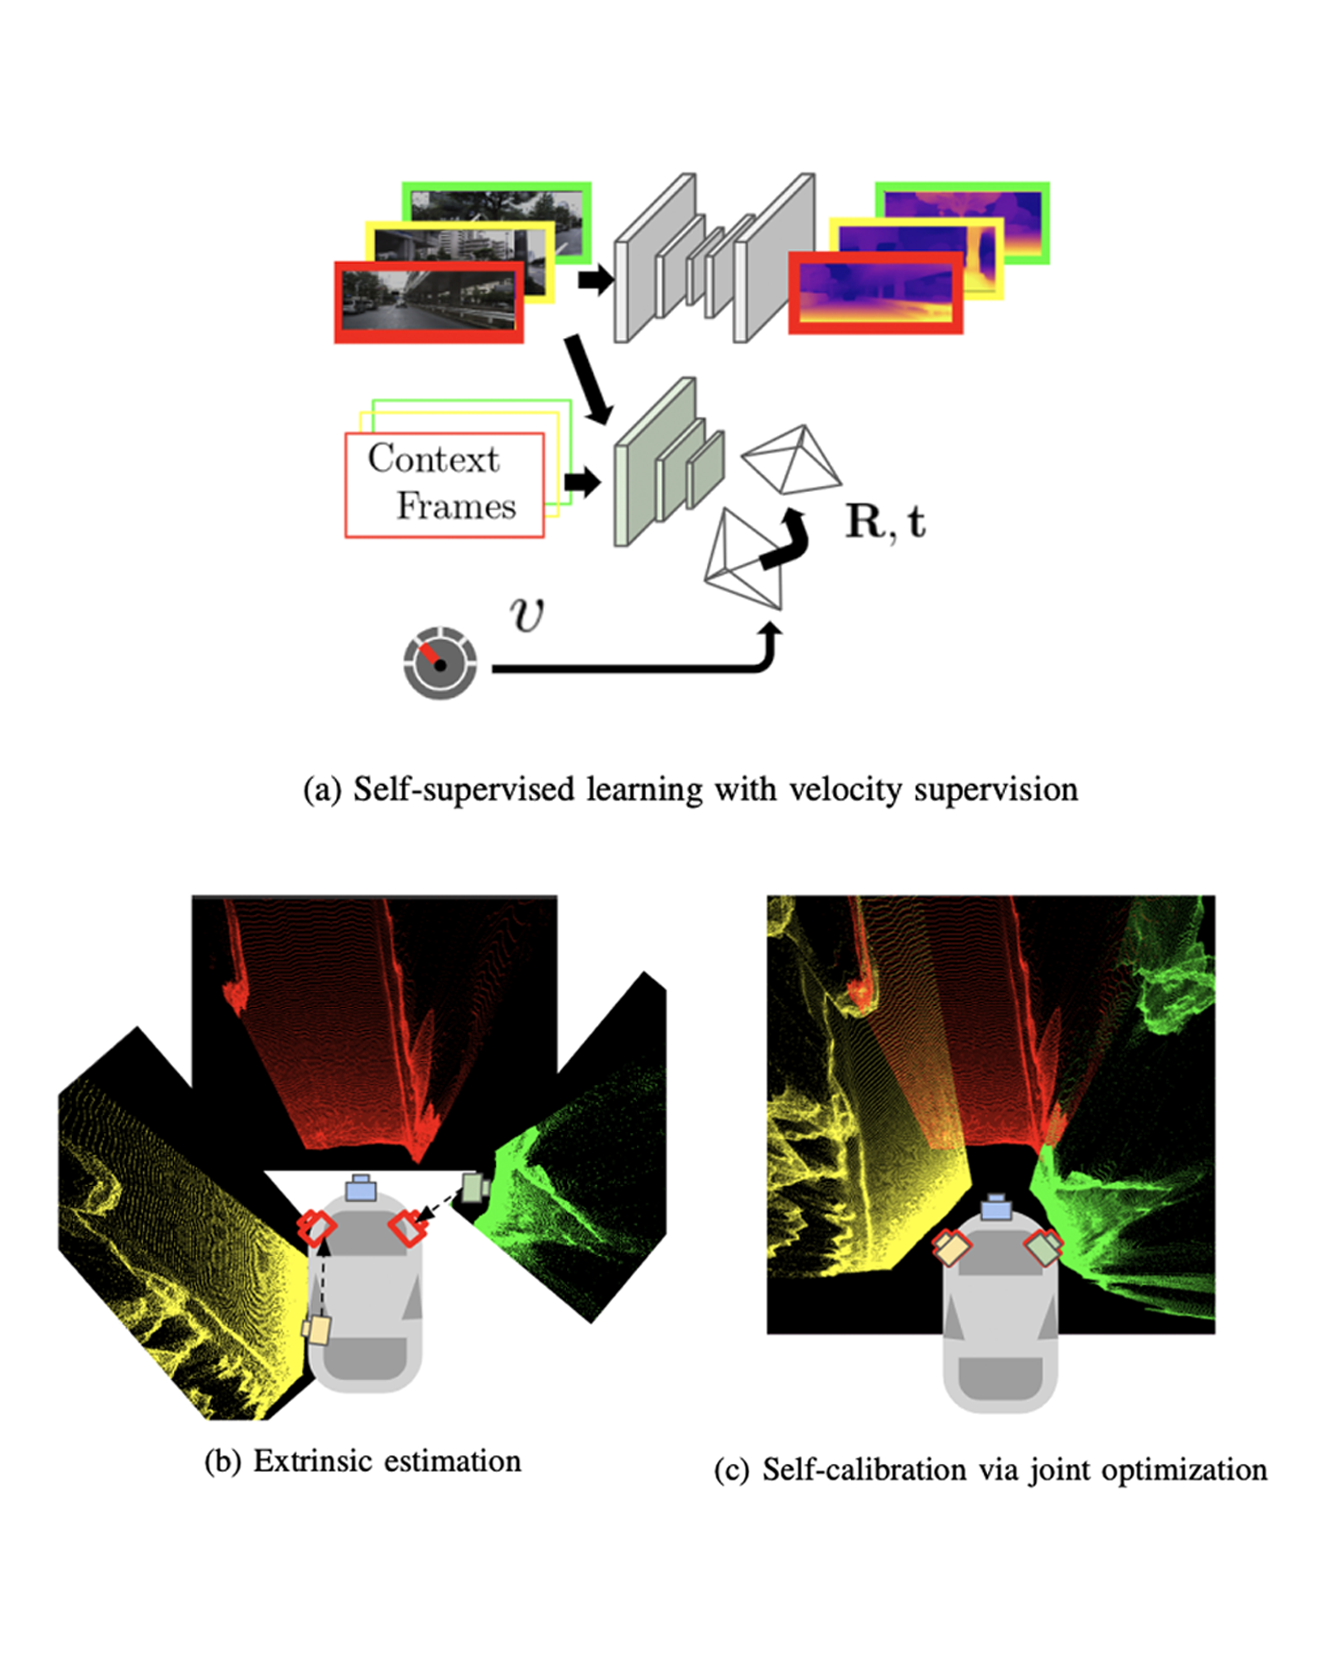
Autonomous vehicles and robots need to operate over a wide variety of scenarios in order to complete tasks efficiently and safely. Multi-camera self-supervised monocular depth estimation from videos is a promising way to reason about the environment, as it generates metrically scaled geometric predictions from visual data without requiring additional sensors. However, most works assume well-calibrated extrinsics to fully leverage this multi-camera setup, even though accurate and efficient calibration is still a challenging problem. In this work, we introduce a novel method for extrinsic calibration that builds upon the principles of self-supervised monocular depth and ego-motion learning. Our proposed curriculum learning strategy uses monocular depth and pose estimators with velocity supervision to estimate extrinsics, and then jointly learns extrinsic calibration along with depth and pose for a set of overlapping cameras rigidly attached to a moving vehicle. Experiments on a benchmark multi-camera dataset (DDAD) demonstrate that our method enables self-calibration in various scenes robustly and efficiently compared to a traditional vision-based pose estimation pipeline. Furthermore, we demonstrate the benefits of extrinsics self-calibration as a way to improve depth prediction via joint optimization. READ MORE
Non-crystalline solid materials have attracted growing attention in energy storage for their desirable properties such as ionic conductivity, stability, and processability. However, compared to bulk crystalline materials, fundamental understanding of these highly complex metastable systems is hindered by the scale limitations of density functional theory (DFT) calculations and resolution limitations of experimental methods. To fill the knowledge gap and guide the rational design of amorphous battery materials and interfaces, we present a molecular dynamics (MD) framework based on machine-learned interatomic potentials trained on the fly to study the amorphous solid electrolyte Li3PS4 and its protective coating, amorphous Li3B11O18. The use of machine-learned potentials allows us to simulate the materials at time and length scales that are not accessible to DFT while maintaining a near-DFT level of accuracy. This approach allows us to calculate amorphization energies, amorphous–amorphous interface energies, and the impact of the interface on lithium ion conductivity. This study demonstrates the promising role of actively learned interatomic potentials in extending the application of ab initio modeling to more complex and realistic systems such as amorphous materials and interfaces. READ MORE
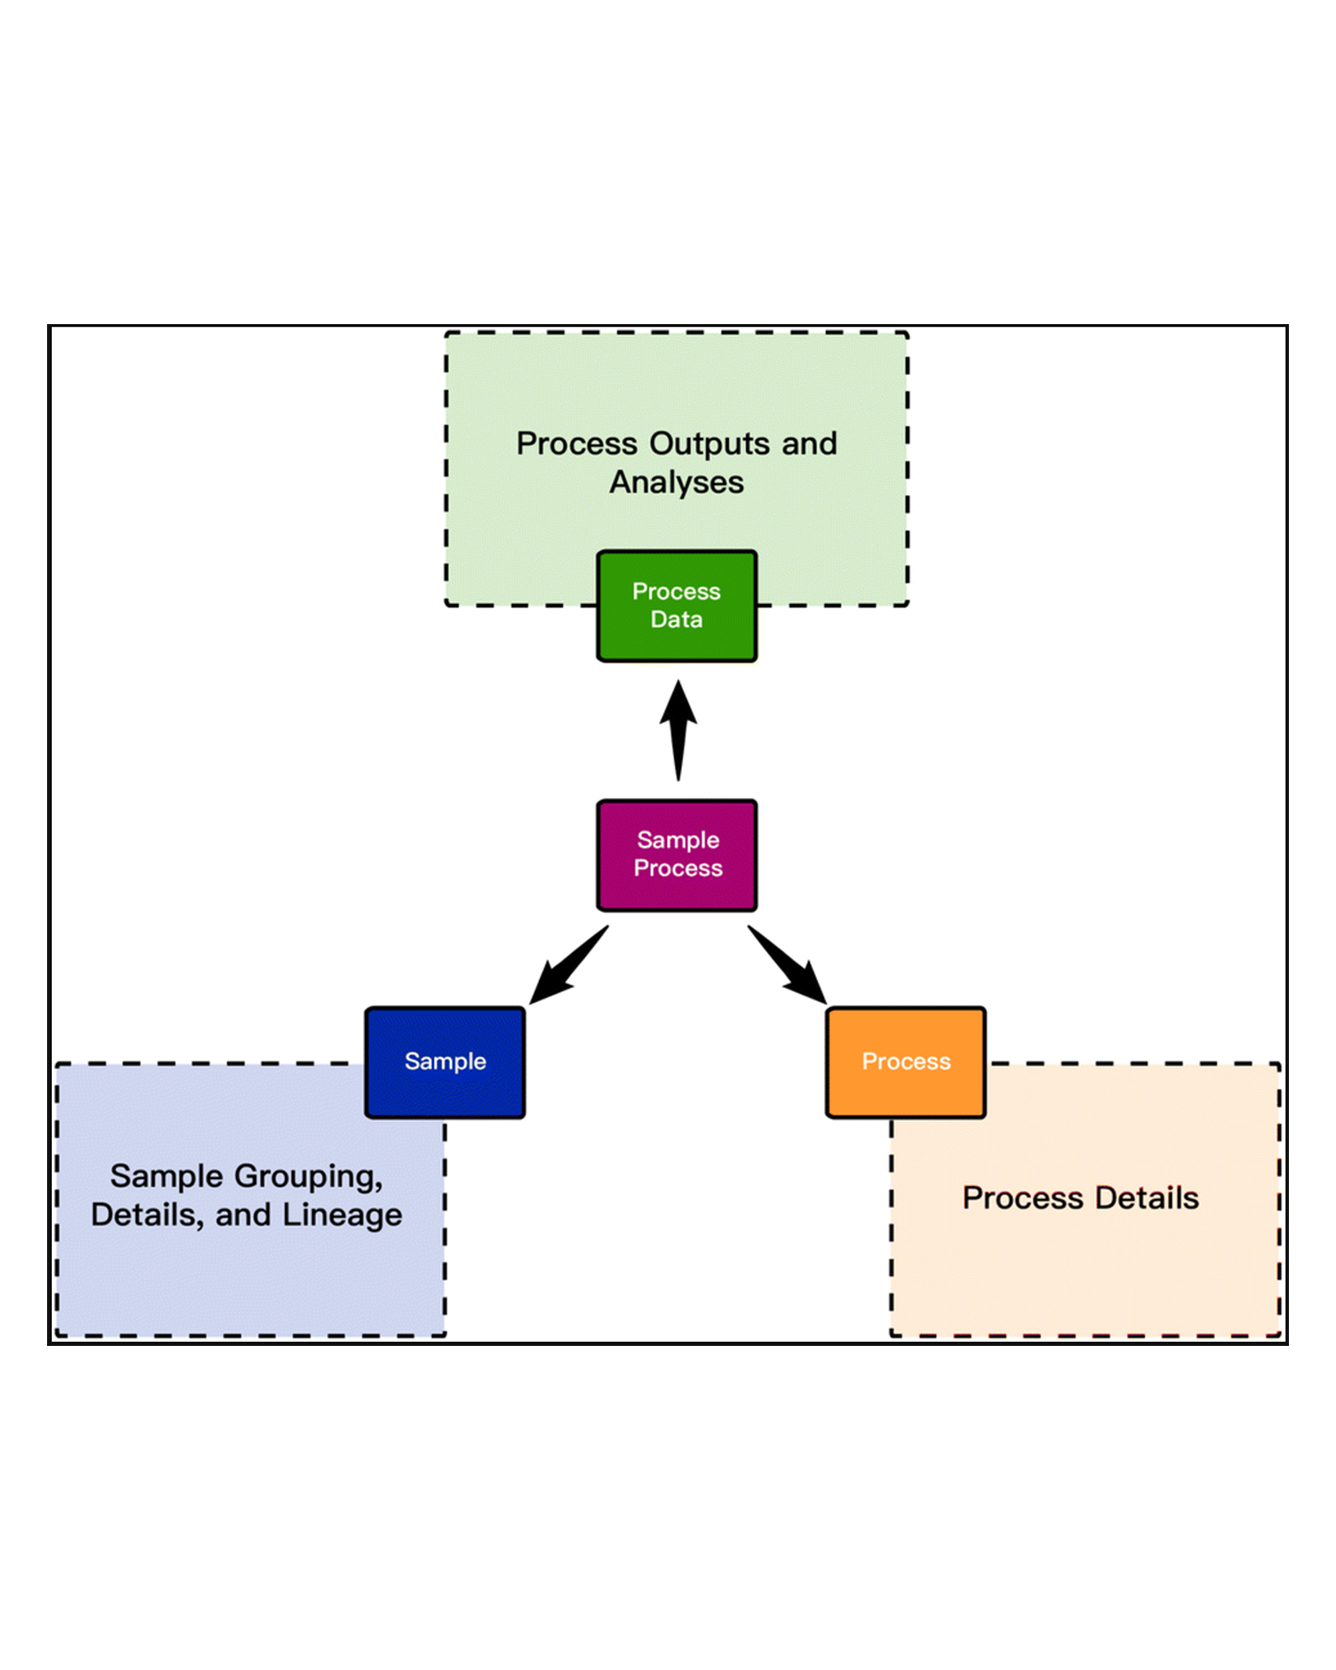
While the vision of accelerating materials discovery using data driven methods is well-founded, practical realization has been throttled due to challenges in data generation, ingestion, and materials state-aware machine learning. High-throughput experiments and automated computational workflows are addressing the challenge of data generation, and capitalizing on these emerging data resources requires ingestion of data into an architecture that captures the complex provenance of experiments and simulations. In this manuscript, we describe an event-sourced architecture for materials provenance (ESAMP) that encodes the sequence and interrelationships among events occurring in a simulation or experiment. We use this architecture to ingest a large and varied dataset (MEAD) that contains raw data and metadata from millions of materials synthesis and characterization experiments performed using various modalities such as serial, parallel, multi-modal experimentation. Our data architecture tracks the evolution of a material's state, enabling a demonstration of how state-equivalency rules can be used to generate datasets that significantly enhance data-driven materials discovery. Specifically, using state-equivalency rules and parameters associated with state-changing processes in addition to the typically used composition data, we demonstrated marked reduction of uncertainty in prediction of overpotential for oxygen evolution reaction (OER) catalysts. Finally, we discuss the importance of ESAMP architecture in enabling several aspects of accelerated materials discovery such as dynamic workflow design, generation of knowledge graphs, and efficient integration of simulation and experiment. READ MORE
Natural Language Processing (NLP), a cornerstone field within artificial intelligence, has been increasingly utilized in the field of materials science literature. Our study conducts a reproducibility analysis of two pioneering works within this domain: "Machine-learned and codified synthesis parameters of oxide materials" by Kim et al., and "Unsupervised word embeddings capture latent knowledge from materials science literature" by Tshitoyan et al. We aim to comprehend these studies from a reproducibility perspective, acknowledging their significant influence on the field of materials informatics, rather than critiquing them. Our study indicates that both papers offered thorough workflows, tidy and well-documented codebases, and clear guidance for model evaluation. This makes it easier to replicate their results successfully and partially reproduce their findings. In doing so, they set commendable standards for future materials science publications to aspire to. However, our analysis also highlights areas for improvement such as to provide access to training data where copyright restrictions permit, more transparency on model architecture and the training process, and specifications of software dependency versions. We also cross-compare the word embedding models between papers, and find that some key differences in reproducibility and cross-compatibility are attributable to design choices outside the bounds of the models themselves. In summary, our study appreciates the benchmark set by these seminal papers while advocating for further enhancements in research reproducibility practices in the field of NLP for materials science. This balance of understanding and continuous improvement will ultimately propel the intersecting domains of NLP and materials science literature into a future of exciting discoveries. READ MORE
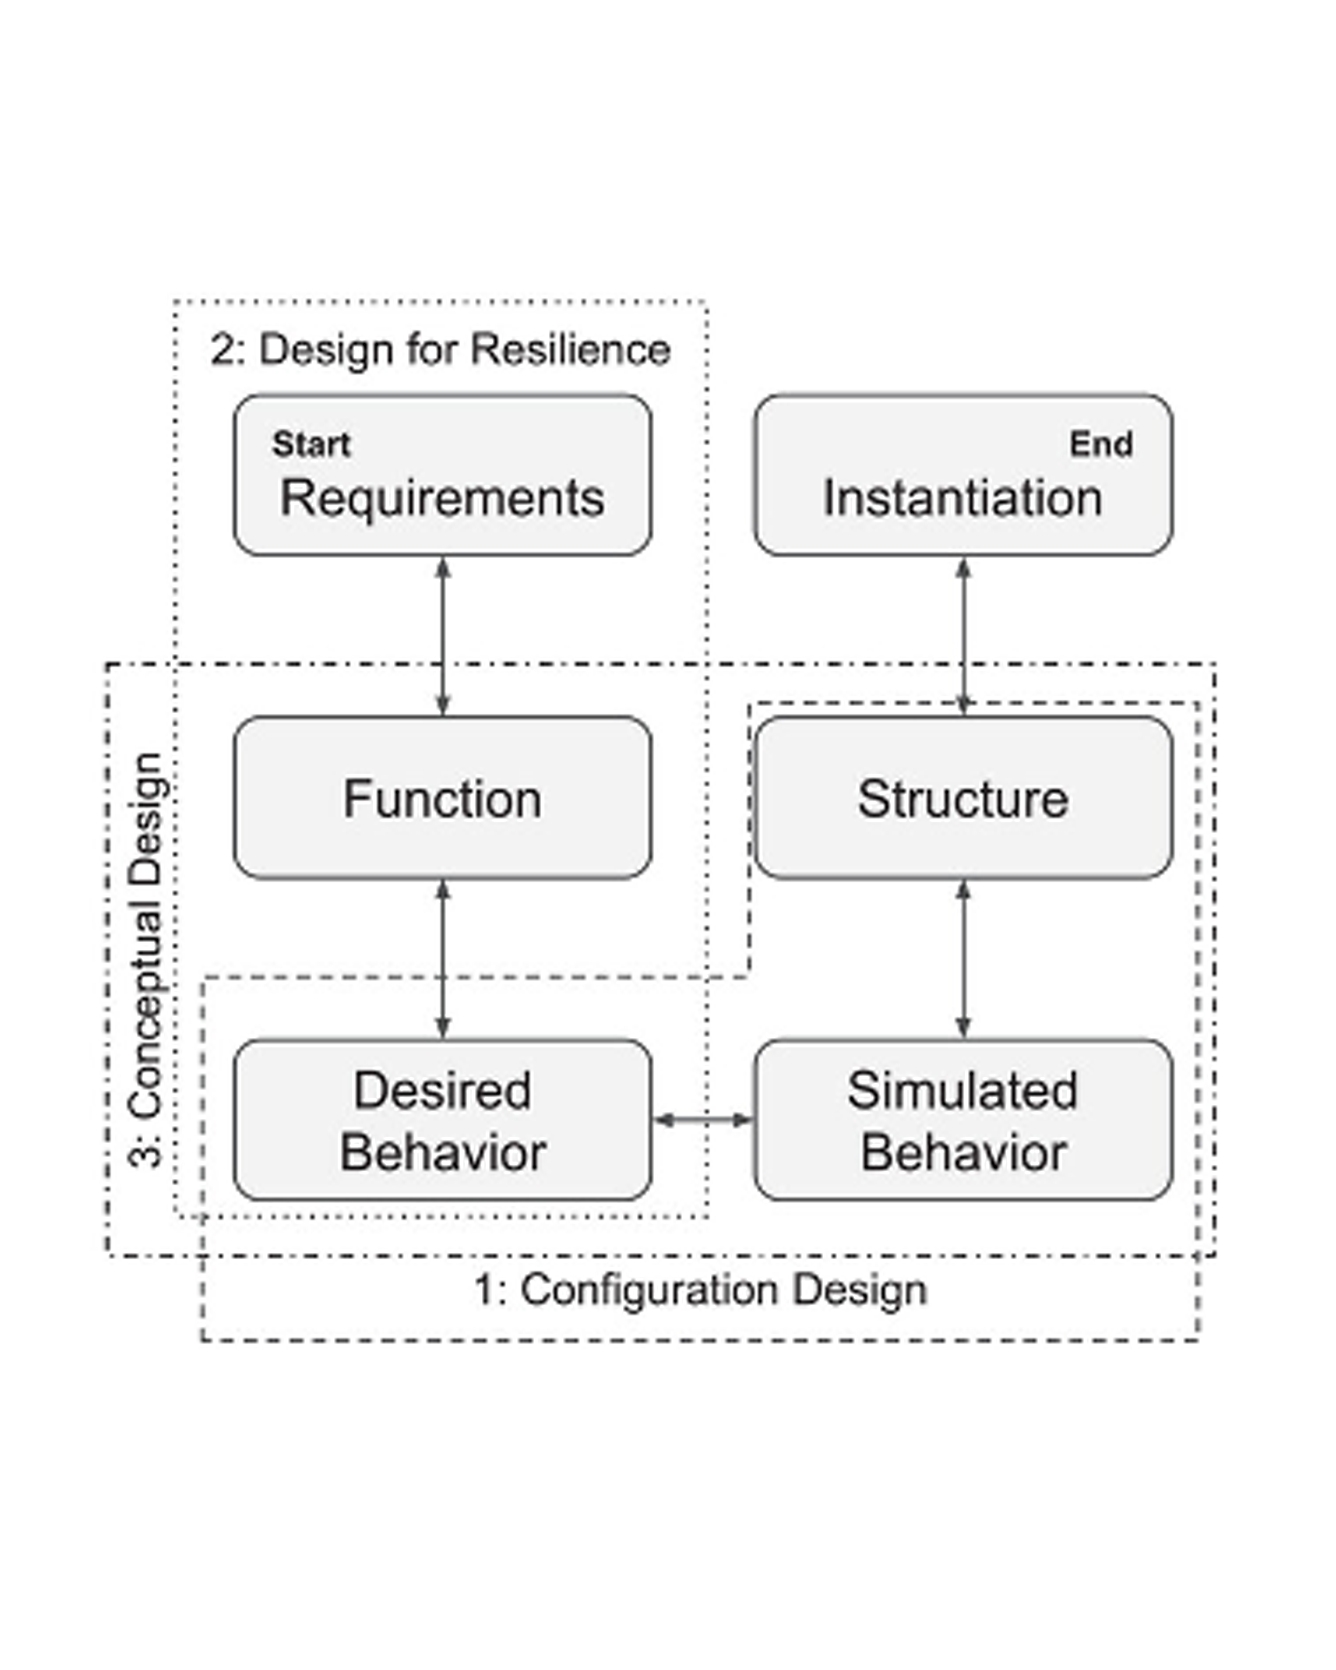
Anticipatory thinking (AT) and design have many commonalities. We identify three challenges for all computational AT systems: representation, generation, and evaluation. We discuss how existing artificial intelligence techniques provide some methods for addressing these, but also fall significantly short. Next, we articulate where AT concepts appear in three computational design paradigms: configuration design, design for resilience, and conceptual design. We close by identifying two promising future directions at the intersection of AT and design: modeling other humans and new interfaces to support human decision-makers. READ MORE
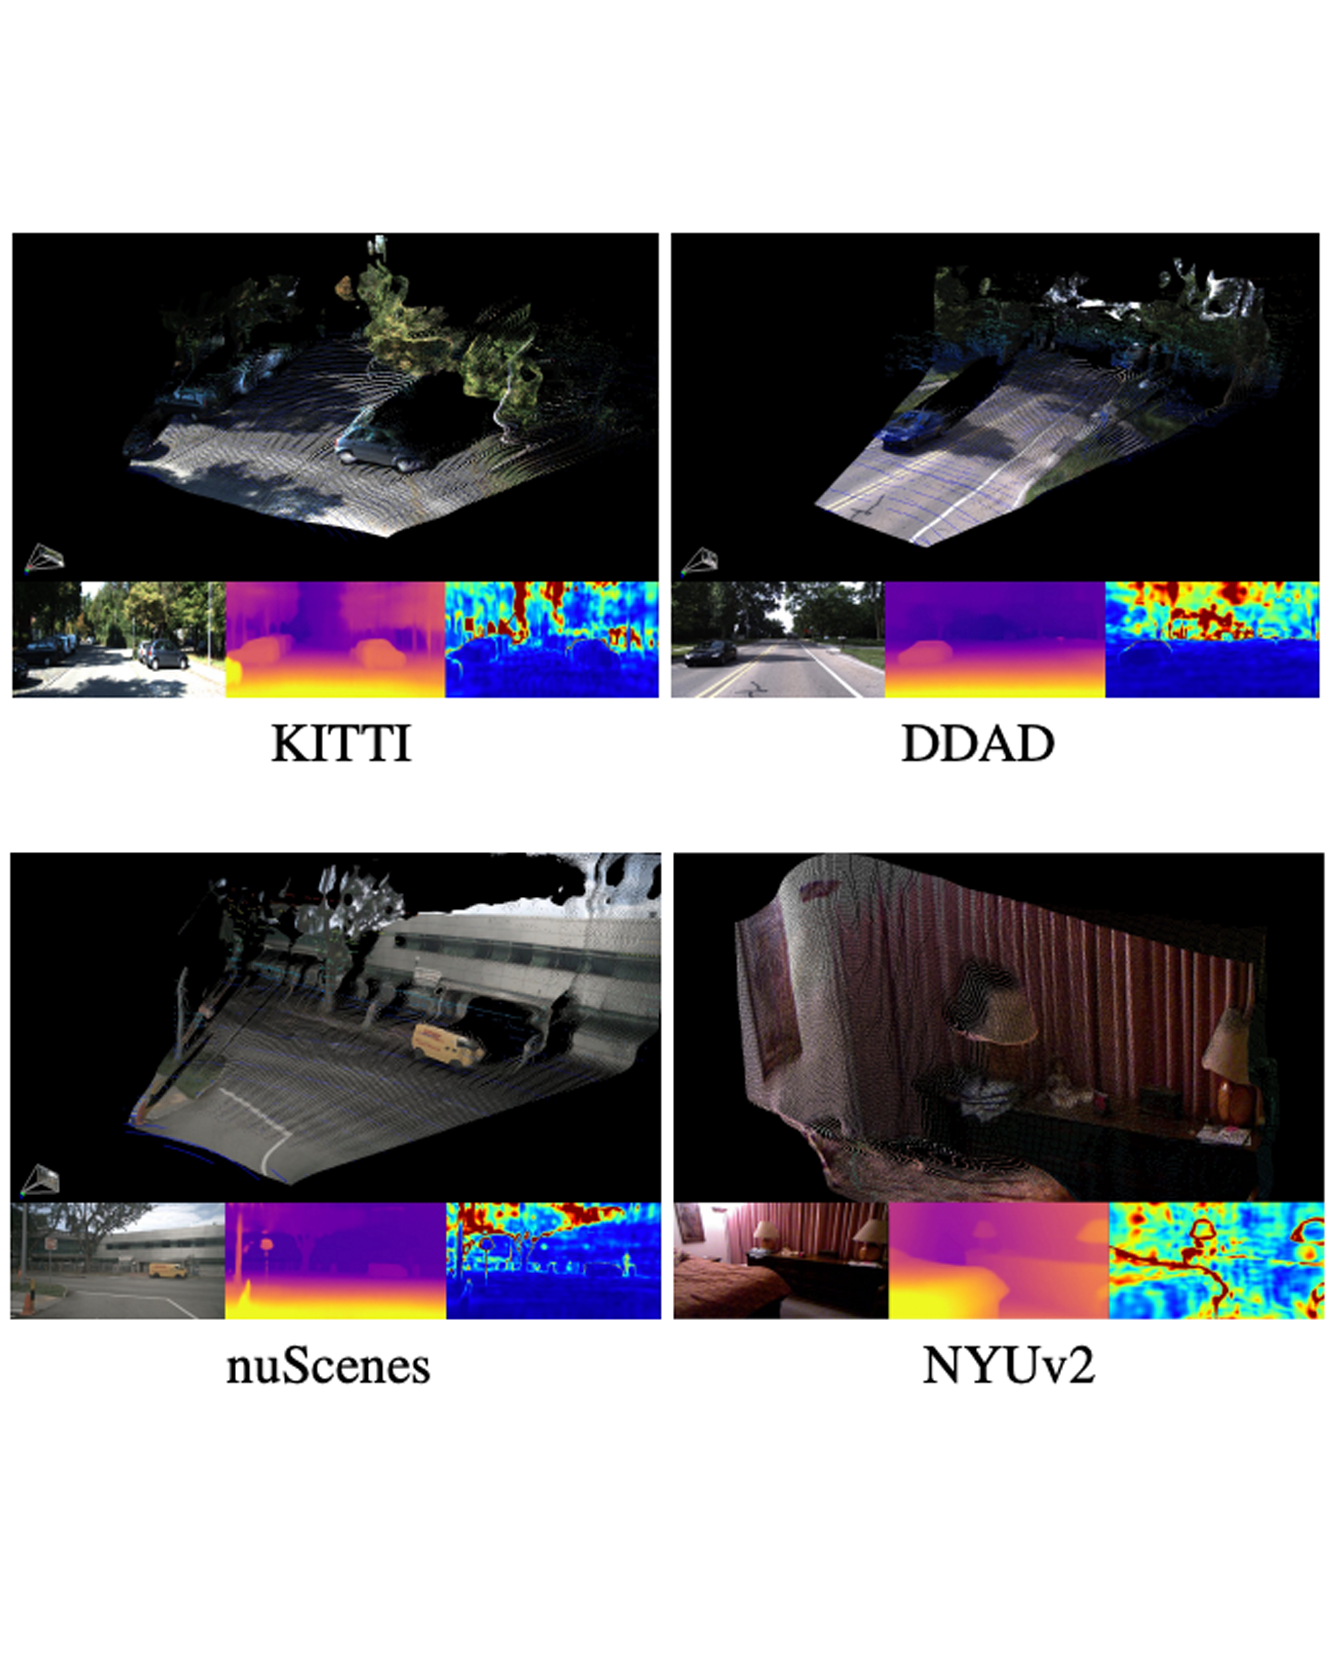
Monocular depth estimation is scale-ambiguous, and thus requires scale supervision to produce metric predictions. Even so, the resulting models will be geometry-specific, with learned scales that cannot be directly transferred across domains. Because of that, recent works focus instead on relative depth, eschewing scale in favor of improved up-to-scale zero-shot transfer. In this work we introduce ZeroDepth, a novel monocular depth estimation framework capable of predicting metric scale for arbitrary test images from different domains and camera parameters. This is achieved by (i) the use of input-level geometric embeddings that enable the network to learn a scale prior over objects; and (ii) decoupling the encoder and decoder stages, via a variational latent representation that is conditioned on single frame information. We evaluated ZeroDepth targeting both outdoor (KITTI, DDAD, nuScenes) and indoor (NYUv2) benchmarks, and achieved a new state-of-the-art in both settings using the same pre-trained model, outperforming methods that train on in-domain data and require test-time scaling to produce metric estimates. READ MORE
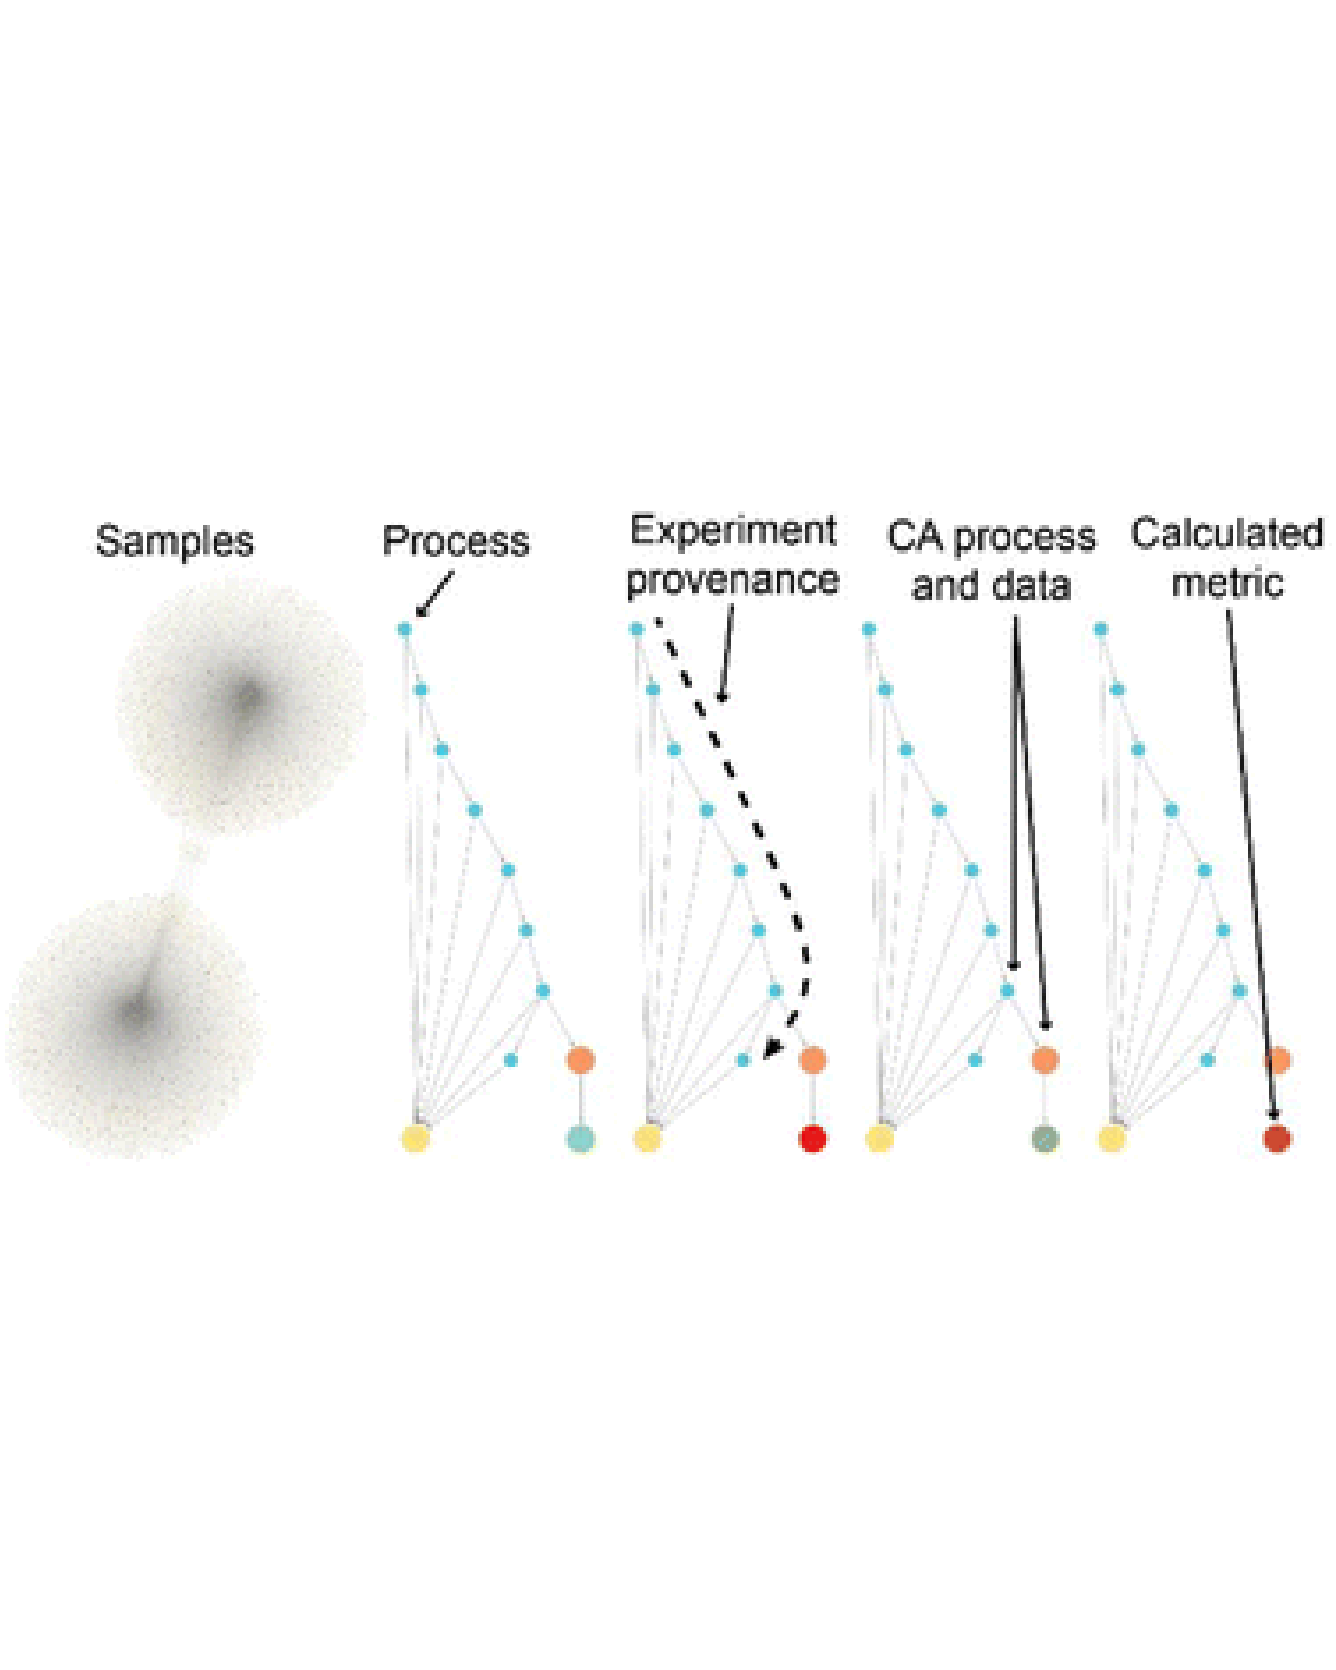
Materials knowledge is inherently hierarchical. While high-level descriptors such as composition and structure are valuable for contextualizing materials data, the data must ultimately be considered in the context of its low-level acquisition details. Graph databases offer an opportunity to represent hierarchical relationships among data, organizing semantic relationships into a knowledge graph. Herein, we establish a knowledge graph of materials experiments whose construction encodes the complete provenance of each material sample and its associated experimental data and metadata. Additional relationships among materials and experiments further encode knowledge and facilitate data exploration. We illustrate the Materials Experiment Knowledge Graph (MekG) using several use cases, demonstrating the value of modern graph databases for the enterprise of data-driven materials science. READ MORE
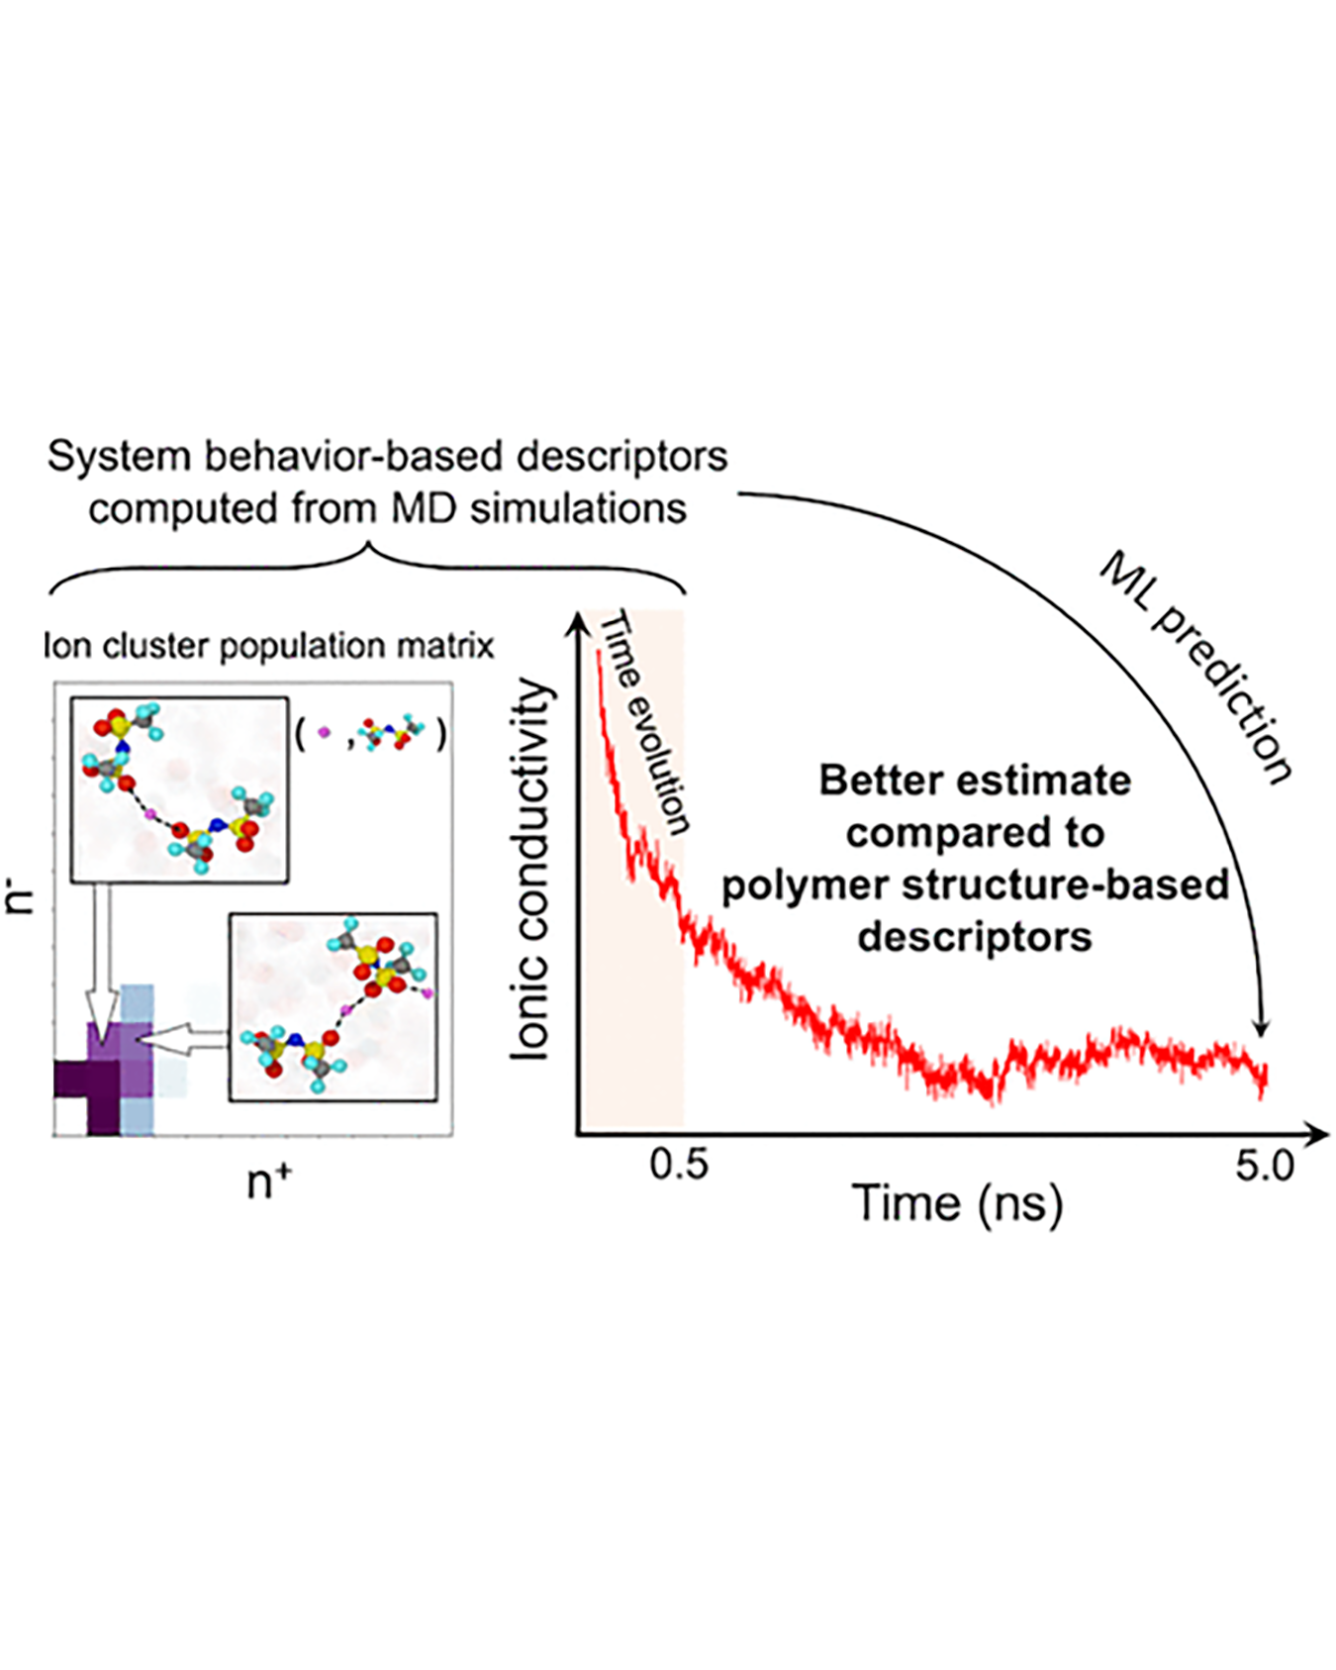
Molecular dynamics simulations are useful tools to screen solid polymer electrolytes with suitable properties applicable to Li-ion batteries. However, due to the vast design space of polymers, it is highly desirable to accelerate the screening by reducing the computational time of ion transport properties from simulations. In this study, we show that with a judicious choice of descriptors we can predict the equilibrium ion transport properties in LiTFSI–homopolymer systems within the first 0.5 ns of the production run of simulations. Specifically, we find that descriptors that include information about the behavior of the system, such as ion clustering and time evolution of ion transport properties, have several advantages over polymer structure-based descriptors, as they encode system (polymer and salt) behavior rather than just the class of polymers and can be computed at any time point during the simulations. These characteristics increase the applicability of our descriptors to a wide range of polymer systems (e.g., copolymers, blend of polymers, salt concentrations, and temperatures) and can be impactful in significantly shortening the discovery pipeline for solid polymer electrolytes. READ MORE
Narrative story generation has gained emerging interest in the field of large language models. The present paper aims to compare stories generated by an LLM only (non-interleaved) with those generated by interleaving human-generated and LLM-generated text (interleaved). The study’s hypothesis is that interleaved stories would perform better than non-interleaved stories. To verify this hypothesis, we conducted two tests with roughly 500 participants each. Participants were asked to rate stories of each type, including an overall score or preference and four facets—logical soundness, plausibility, understandability, and novelty. Our findings indicate that interleaved stories were in fact less preferred than non-interleaved stories. The result has implications for the design and implementation of our story generators. This study contributes new insights into the potential uses and restrictions of interleaved and non-interleaved systems regarding generating narrative stories, which may help to improve the performance of such story generators. READ MORE